Object, File and Block Storages
From the book I Am Datapedia!, published here free by the author.
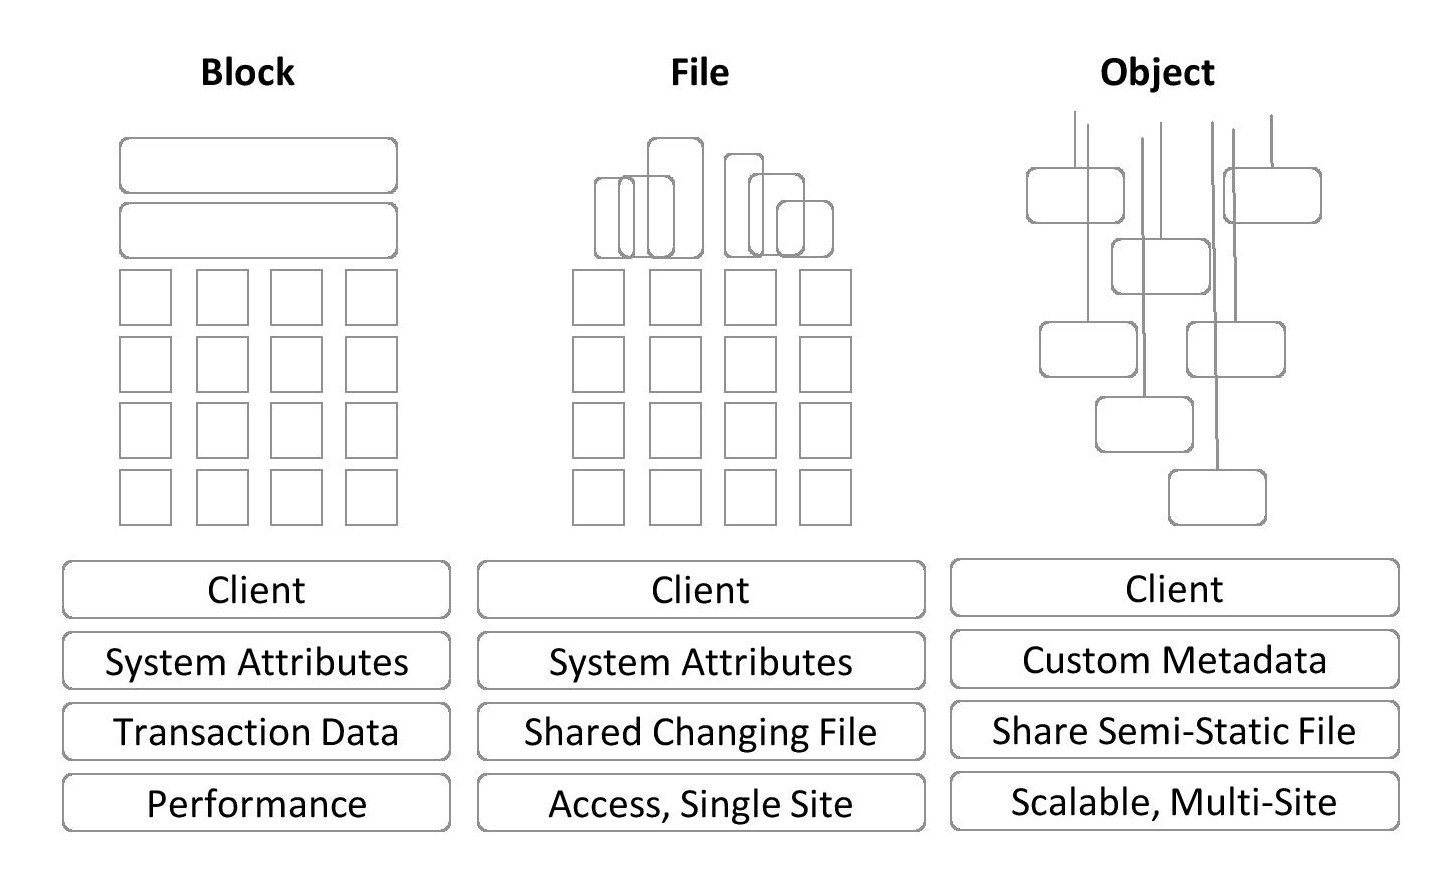
- Object Storage considers all types of data as an object. Here data is stored in a flat open storage area, with no folders or subfolders concept, along with its metadata and unique identifier which forms a storage pool keeping all details about that data near to it.
- File Storage keeps data as one piece of information inside folders and subfolders which is in a way is in Hierarchy mode, in contrast with Object storage e.g., you must remember how we used to keep manual papers in files in our school days. It’s the same concept here. So, when you need any specific data, you just need to know the location or path of the folder.
- Block storages consider a file as a single block of data and each block is stored as a separate piece of information. A unique address is given to each block for reference. Traditional databases are stored in blocks, and at the backend Hadoop files are also stored in blocks.
Nowadays, in the era of big data, data lake, delta lake, data lakehouse etc., Cloud companies are using Object storage as their de-facto storage e.g., S3 (AWS), ADLS (Azure), Teradata and Oracle are calling it Object Storage itself.
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
Useful0
Insightful0
Actionable0
Thought-provoking0
Inspiring0
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.