Data Classification,Categorization and Data Clustering
From the book I Am Datapedia!, published here free by the author.
These two terms are used in Machine Learning for Data Mining and Data Science models. As we all know, within Machine Learning, there are Supervised and Unsupervised Learning methods.
Data Classification/Categorization=Supervised Learning
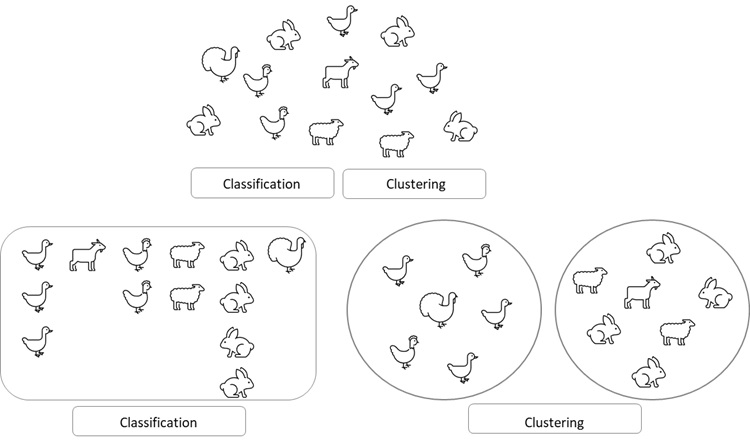
Both these terms are used for patterns identification before complex algorithms come into action.
Classification is done based on the uniqueness of the data where e.g., all animals are tagged separately whereas Clustering is done based on the characteristics e.g., 1) Animals with 2 legs 2) Animals with 4 legs.
- Data Classification uses labeled data whereas Data Clustering uses unlabeled data.
- The most popular Data Classification algorithms in data mining are the K-Nearest Neighbor and decision tree algorithms.
- The two common Data Clustering algorithms in data mining are K-means clustering and hierarchical clustering.
- Data Classification output is known.
- Data Clustering out is unknown.
- Training data is provided for Data Classification.
- No training data is provided for Data Clustering.
These two 2 terms are heavily used in Data Mining and Data Science.
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.