Data Tokenization
From the book I Am Datapedia!, published here free by the author.
Data Tokenization is mostly mixed up with Data Masking but there are major maintenance differences.
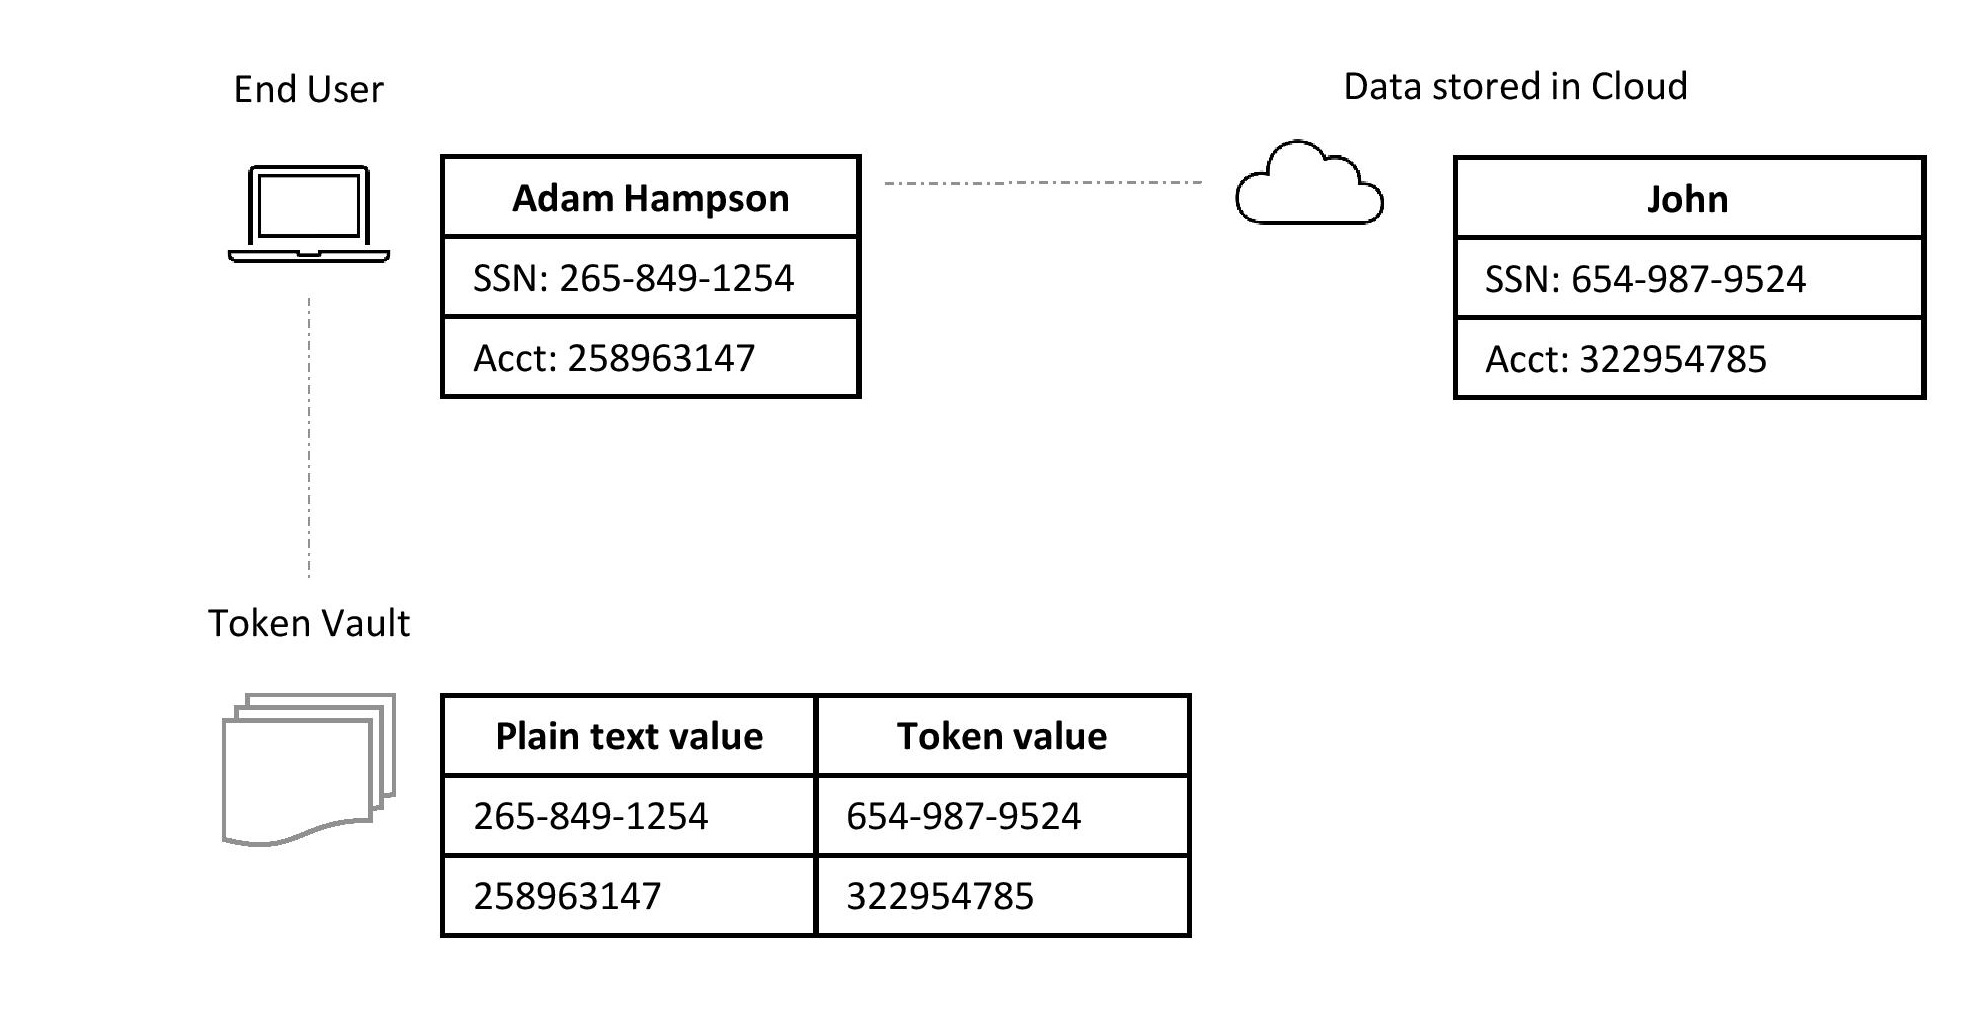
We know how data masking works i.e., it changes data with random values, means to hide original data so if data reaches into wrong hands, one should not be able to identify the individual to whom the record refers.
Data Tokenization also replaces sensitive data with unique system generated value called Token but during the process original data + token along with mapping details are stored in a Token Vault somewhere externally for safe keeping.
As Token replaces original data in actual data store, its mapping details are still safe in Token Vault so actual data is always reversible in contrast with Data Masking where after sensitive data is randomly changed it’s no longer reversible.
A quick example for experienced Data Warehousing folk is Surrogate Key where original business keys are replaced with unique autogenerate values, but original data is not touched. In Data Warehousing Surrogate Key resides along with actual data whereas in Data Tokenization, Surrogate Key resides in Token Vault.
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.