Once you sign in, your details will show here.
Knowledge Hub
+ New Topic
Filter (1)
Sort
383 topics · I Am Datapedia! · 10 shown
Show allEvery topic is free to read. A free account also lets you search the topics, react to a topic and comment under it.
- I Am Datapedia!
Data Foundations
What is Data?
Data has become one of the most powerful words in our modern vocabulary. It drives our world, impacting decisions in industries, governments, and our daily lives. But what exactly is data? How do we define it in a way that captures its full impact and utility?
Mustafa Qizilbash
“Features and Activities of an Object is Data.”This phrase encapsulates data’s essence. But let’s break down what it really means.
Origins and Traditional Definitions
The word "data" originates from the Latin word datum, which means "something given". This concept persists in how we perceive data today: it’s a foundational input, a starting point. In French, for example, data is referred to as données, highlighting its roots as something "given" or granted for analysis.
If you look up data in Wikipedia, you might find it defined as "individual facts, statistics, or items of information, often numeric." More formally, data is a set of values related to qualitative or quantitative variables about one or more entities or objects. In this sense, each "datum" represents one specific value or measurement.
7 min read3 viewsMore
- I Am Datapedia!
Data Foundations
What is an Entity?
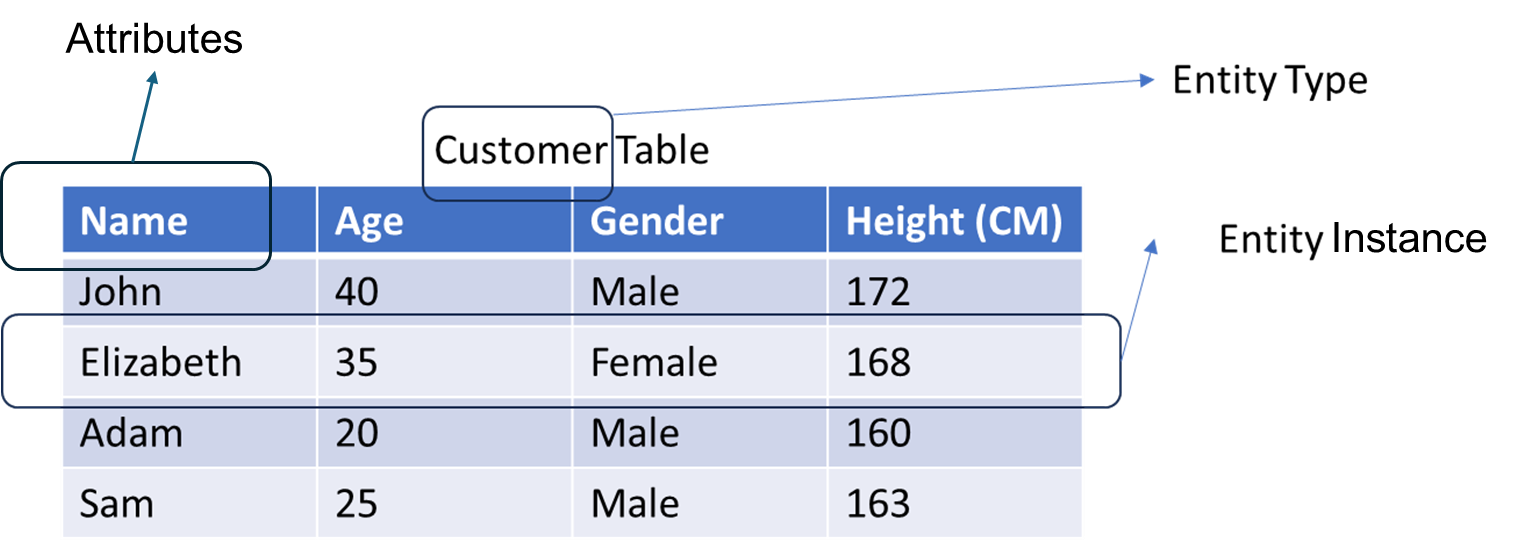
In the world of data and databases, the term entity is foundational yet often misunderstood. To build reliable data systems, it is essential to understand what an entity is and how it is structured. This chapter explores the concept of an entity and breaks it down into its three core components: Entity Type, Entity Attributed and Entity Instance.
Let’s decode it.
What Is an Entity?
An entity is anything that can be uniquely identified and described. In data modelling, an entity typically refers to a real-world object, person, concept, or event that holds relevance within a system, such as a student, a book, or a transaction.
Entities are the fundamental building blocks of structured data models. To model and manage them effectively, we categorize entities into two levels:
- Entity Type: the blueprint or template
- Entity Attribute: the properties
- Entity Instance: the real-world, data-filled object
1. Entity Type – The Blueprint
4 min readMore
- I Am Datapedia!
AI and Machine Learning
Entity Recognition
Entity Recognition, commonly known as Named Entity Recognition (NER), is a technique used to identify and extract meaningful entities from unstructured text. It is also referred to as entity identification or entity extraction. While entity recognition has long been appreciated in data modeling, particularly during conceptual modeling when identifying core business entities, it plays an equally critical role in the data science domain.
In traditional structured systems, entities such as Customer, Product, Order, or Invoice are clearly defined within database schemas. However, modern organizations generate enormous volumes of unstructured data from social media posts, emails, PDF files, Word documents, comment columns, chat transcripts, and even video or audio content converted into JSON or text formats. For data modelers, this unstructured layer represents one of the greatest challenges when designing robust data models.
4 min readMore
- I Am Datapedia!
Data Foundations
Tables, Columns and Rows
Table, Column and Rows are one of the most basics of Data World but it’s worth explaining.
Let’s try to understand with an example, let’s say family is a table, how? Consider, you have 6 members in your family i.e., Grandfather = 1, Grandmother = 1, Father = 1, Mother = 1, Son = 1, Daughter = 1
Above is a standard average traditional family for most of us. Now, each of above members will have Name, Relationship and Date of Birth, right? These details or information are called properties and attributes of each family member and are called Columns or Fields in a table.
Now, when we say Name of the eldest person in family is John, his relationship in family is Grandfather, and his Date of Birth is 1st January 1950. These details or information about one person in a family is called a Row.
Same way, when we have details or information about all the family members, we can say, we have multiple rows.
1 min readMore
- I Am Datapedia!
Data Modeling and Design
Primary and Foreign Keys
Primary Key is also known as Pkey, and Foreign Key is also known as Fkey. These are one of the most important terms without which a proper Data Model cannot be created.
We have understood what a table is. Now, the next step is to understand, if there is more than one table then how to join both. In the topic ‘Tables, Columns and Rows’ we used an example of table ‘Family’. Let’s use the same table here with an additional column i.e., Birth Location.
Table Name: Family
Now let’s say, to save space in Family table as we can see ‘United State of America’ has been used many times so how about creating another table where let’s store lengthy country names and in Family tables, let use country code instead with there is another table called as Birth Location.
Table Name: Birth Location
Now, let’s update the Family table to reflect country code instead of country name.
Table Name: Family
Now, the problem is column ‘Birth Location’ have country code so how to find out which country name refer to ‘001’. Let’s declare ID in Birth_Location table as Pkey and Location_ID in Family table as Fkey.
2 min readMore
- I Am Datapedia!
Data Foundations
Types of Data
In data management, there are three fundamental data types: structured, semi-structured, and unstructured. These data types can originate from numerous sources, including databases, mobile applications, social media platforms, sensors, logs, CCTV footage, radio signals, and more. While structured and unstructured data are widely recognized, the classification of semi-structured data often leads to debate.
Structured Data
Structured data refers to information organized in a predefined format, typically consisting of rows and columns. For instance, imagine an “employee-contact-details” table containing fields such as employee code, email, mobile, LinkedIn URL, Instagram, and Twitter. Although not every employee will have complete details, the table structure remains intact when exported, with each row containing a set number of columns, even if some fields are empty. For example, a dataset with 6 columns and 10 rows will consistently display this format, regardless of missing data entries.
3 min readMore
- I Am Datapedia!
Data Quality
Good vs Bad Data
Good data in the data world possesses several essential qualities that contribute to its reliability and effectiveness. Firstly, it is accurate, ensuring that the information it represents aligns with the real-world context it intends to portray, free from errors or inconsistencies. Completeness is another hallmark of good data, implying that it includes all necessary details without any missing or incomplete records. Consistency is maintained throughout, following standardized formats and structures, facilitating uniformity and coherence. Relevance ensures that the data is directly applicable to its intended purpose, meeting the specific goals of data analysis or application. Timeliness is a key aspect, as good data is up to date, reflecting the most recent and relevant information. Reliability is associated with trustworthiness, ensuring the data is unbiased and collected through reliable methods. Validity is maintained by adhering to predefined rules and standards, and accessibility ensures that authorized users can easily retrieve and utilize the data.
4 min readMore
- I Am Datapedia!
AI and Machine Learning
Causality Data
Causality Data in the data world refers to information that helps establish a cause-and-effect relationship between different variables or events. In other words, it involves understanding the influence or impact that changes in one variable have on another.
Causality is a fundamental concept in statistics and data analysis, especially when trying to make sense of complex systems or phenomena. Establishing causal relationships is important for drawing meaningful conclusions and making informed decisions. However, it is essential to word that correlation does now no longer imply causation. While two variables may be correlated, it doesn't necessarily mean that one causes the other.
In the context of data science and analytics, establishing causality often involves advanced statistical methods and experimentation.
Here are a few key points related to causality data:
- Experimental Design: Controlled experiments, where researchers manipulate one variable while keeping others constant, are often used to establish causality. This allows for the isolation of the variable of interest and helps draw conclusions about its impact.
- Observational Studies: In cases where controlled experiments are not feasible, observational studies are conducted to analyze existing data. However, establishing causality in observational studies can be more challenging due to potential confounding factors.
- Counterfactuals: Causality often involves comparing what happened to what might have happened in the absence of a particular intervention or change. This comparison is known as a counterfactual analysis.
- Temporal Order: Causality requires that the cause precedes the effect in time. Observing a temporal order between variables is an important aspect of establishing causation.
- Statistical Techniques: Various statistical techniques, such as regression analysis, propensity score matching, and instrumental variable analysis, are employed to analyze data and infer causal relationships.
4 min readMore
- I Am Datapedia!
AI and Machine Learning
Inference Data
Inference Data refers to the data produced by ML process of drawing conclusions, making predictions, or generalizing information based on the analysis of a features dataset. It is a crucial step in extracting meaningful insights from data and often involves the application of statistical methods.
Let's decode it.....
Imagine you want to know something about a big group of students, like all the students in your school. Instead of asking every single student (which could be too much work), you ask a smaller group. This smaller group is like a sample. In simpler terms, inference is like making smart guesses about everyone by looking at a few representative friends first. It's a bit like saying, "I can figure out what most people like, by asking a few of them because they're probably a lot like everyone else."
Inference data is a process of drawing meaningful conclusions about a larger dataset based on observed data, and it is a fundamental aspect of statistical reasoning and data analysis in various domains.
2 min readMore
- I Am Datapedia!
Reference and Master Data
Master andReference Data Management
If you would like to step into the data domain, the most significant topics anybody must recognize are Metadata, Master & Reference Data Management. If you grasp these areas, one will require 80% less time to orchestrate any Data Solution.
Master Data refers to the core datasets that are essential for business operations and act as the foundation for all other data within an organization. These datasets typically represent key entities or subjects that are critical to the functioning of the business and are used across multiple systems, processes, or applications.
A unique characteristic of Master Data is that it cannot exist independently, it relies on the existence of specific entities or attributes to be meaningful. For example, you cannot have a customer master record without defining key attributes such as the customer’s name, address, and unique identifier (e.g., customer ID). Similarly, a product master record cannot be created without information such as the product name, SKU, or category.
6 min readMore
Build a strong foundation in Data & AI
Follow the Data Foundations learning path (Beginner to Advanced).