Data Entropy
From the book I Am Datapedia!, published here free by the author.
Entropy term is normally used in Data Science domain.
- Where finding unexpected outcomes is the aim
- Where surprises are welcomed
- Where results are analyzed based on probability ratio, the lower the probability the better it is.
- Where informative information is something which wasn’t known
Types
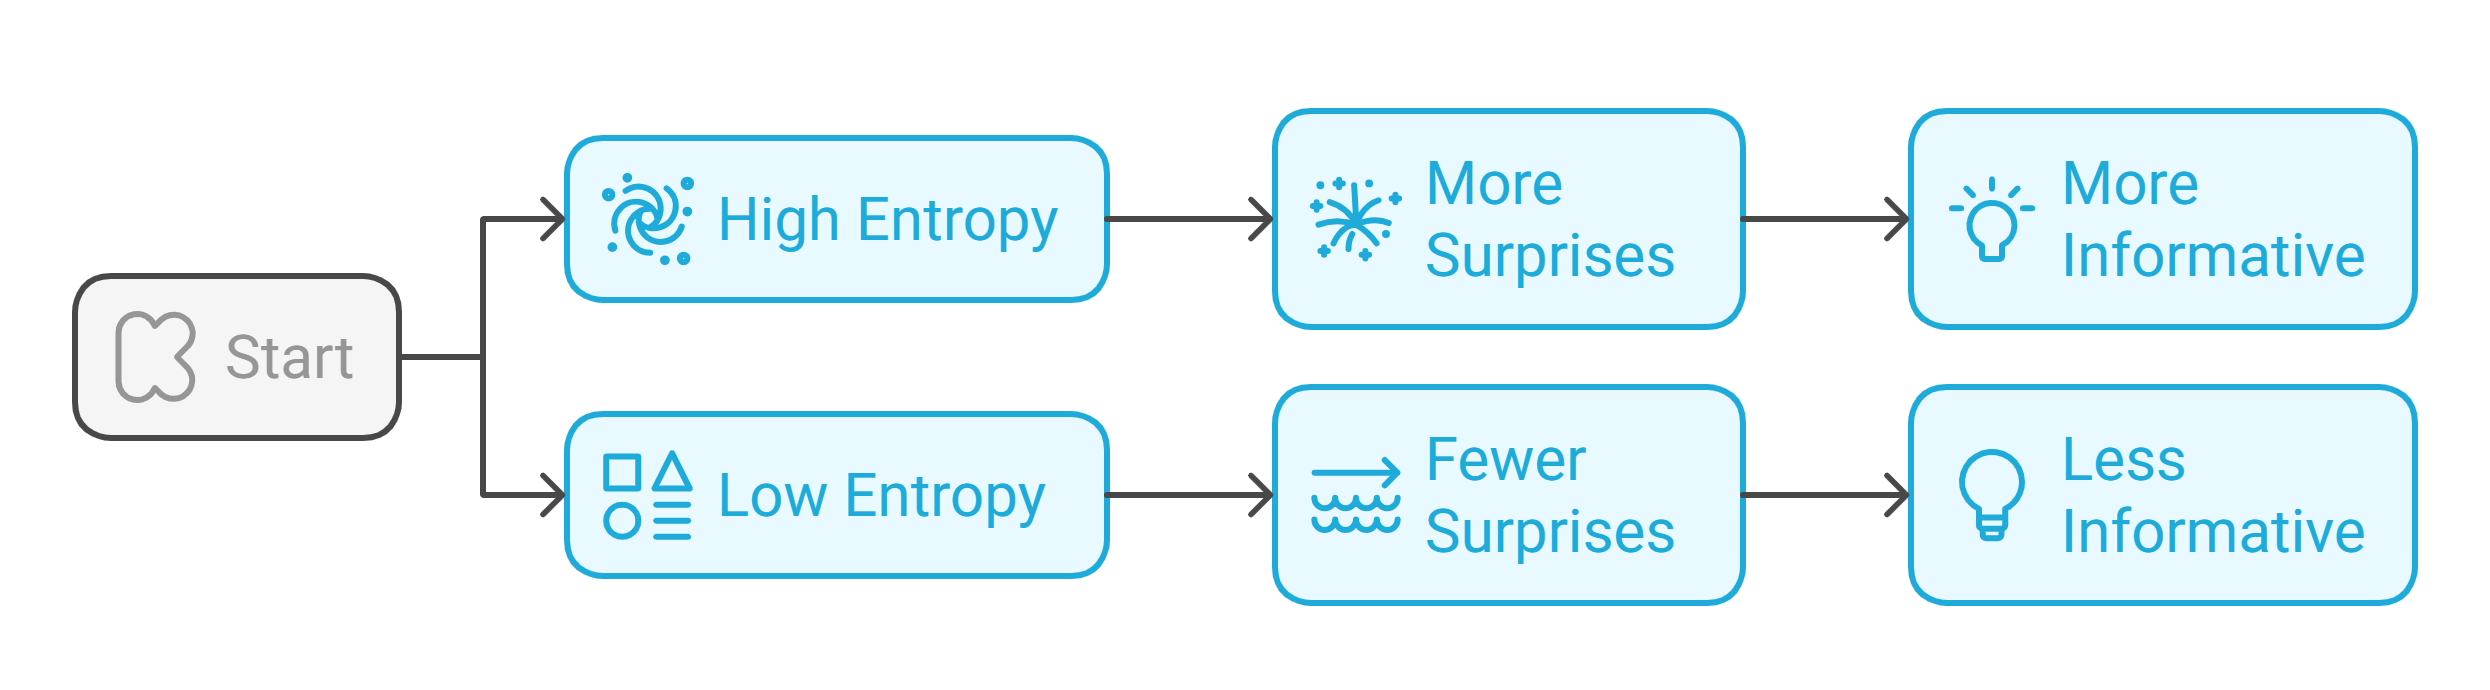
- High Entropy means, more surprises, more unexpected values are considered more informative.
- Low Entropy means, less surprises, less unexpected values are considered less informative.
‘Entropy is also called as Extreme Disorder of values.’
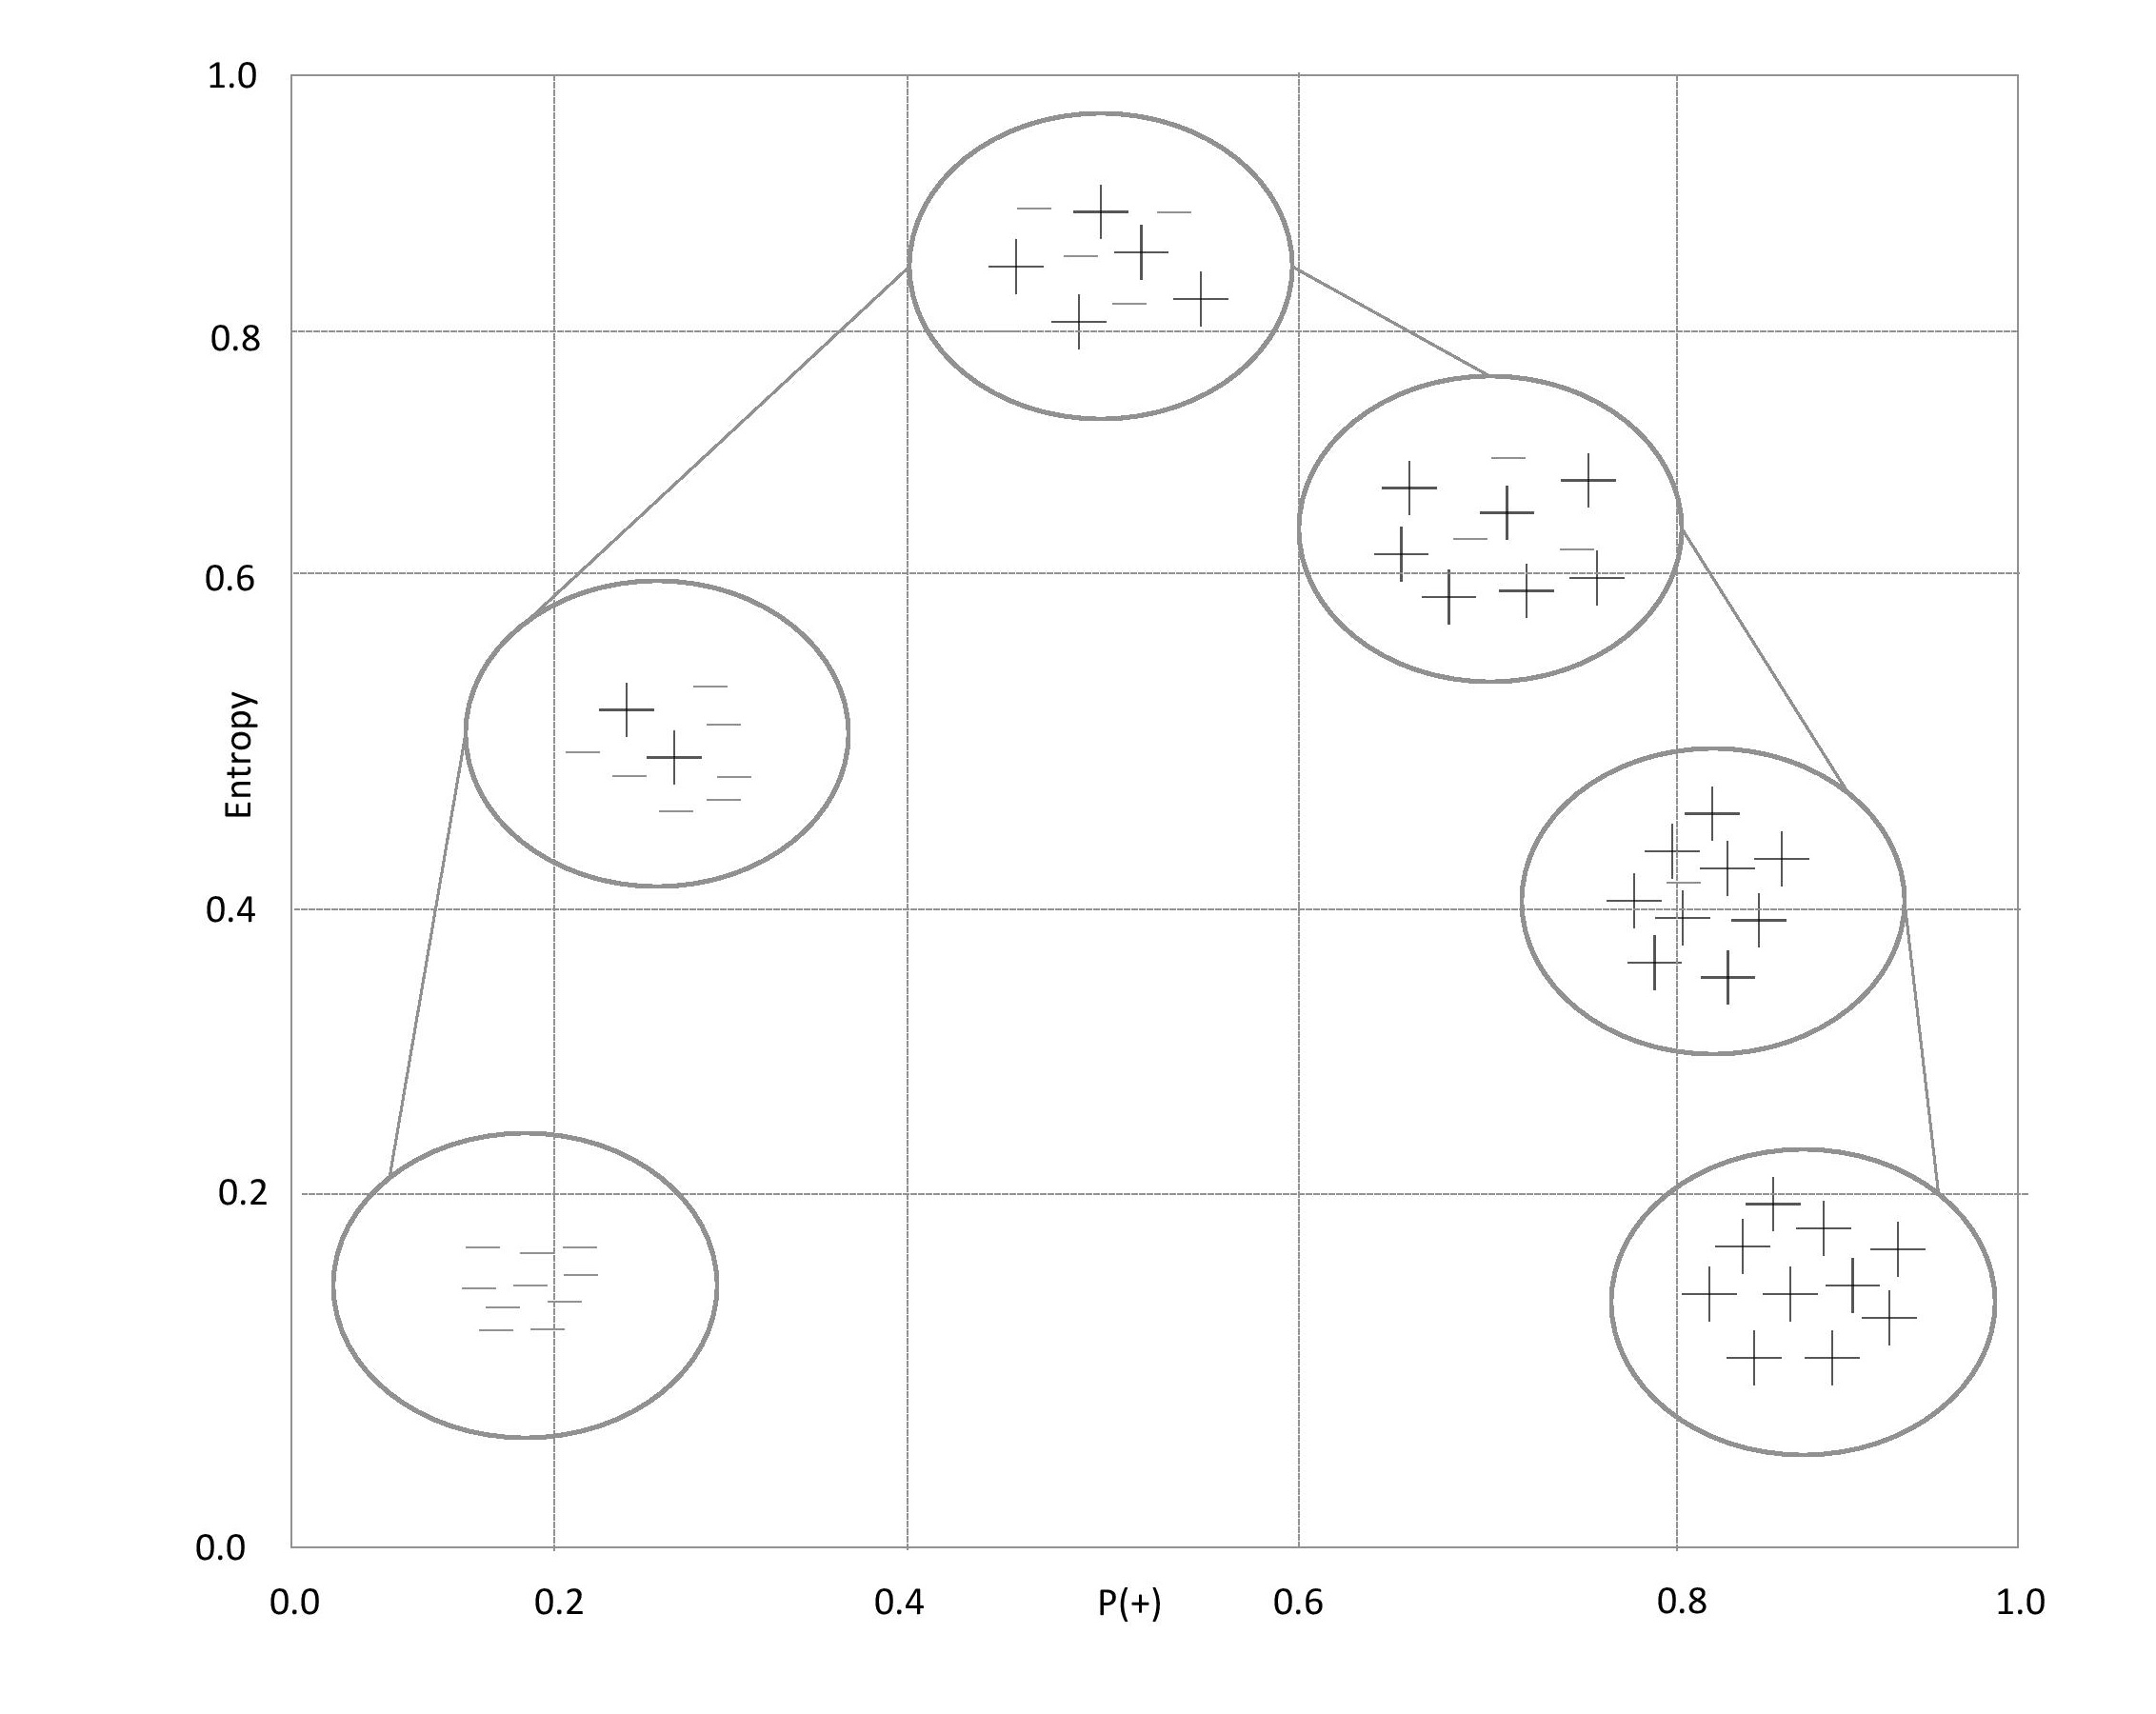
Referring to the image, we can see at the starting point all the signs are MINUS, then in the middle there are 50/50 signs of PLUS & MINUS and right at the end all the signs are PLUS. At those extremes left, middle and right corners, the Entropy is at the lowest, so no surprises are expected so nothing much for Data Scientists to predict right. But in 2nd, 4th, and 5th circles, it’s difficult to say how many PLUSES(s) and MINUS(s), if values are not visible, at this points Entropy is at the highest.
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.