Data Identification
From the book I Am Datapedia!, published here free by the author.
Data Identification is the pre-requisite for Data Anonymization. How?
Data Identification is about those set of details which assist in identifying an entity or individual. These details can be direct details like name, contact number, address, credit card number etc. or can be indirect details like unique identification number which assist to connect with other datasets to identify an entity or individual.
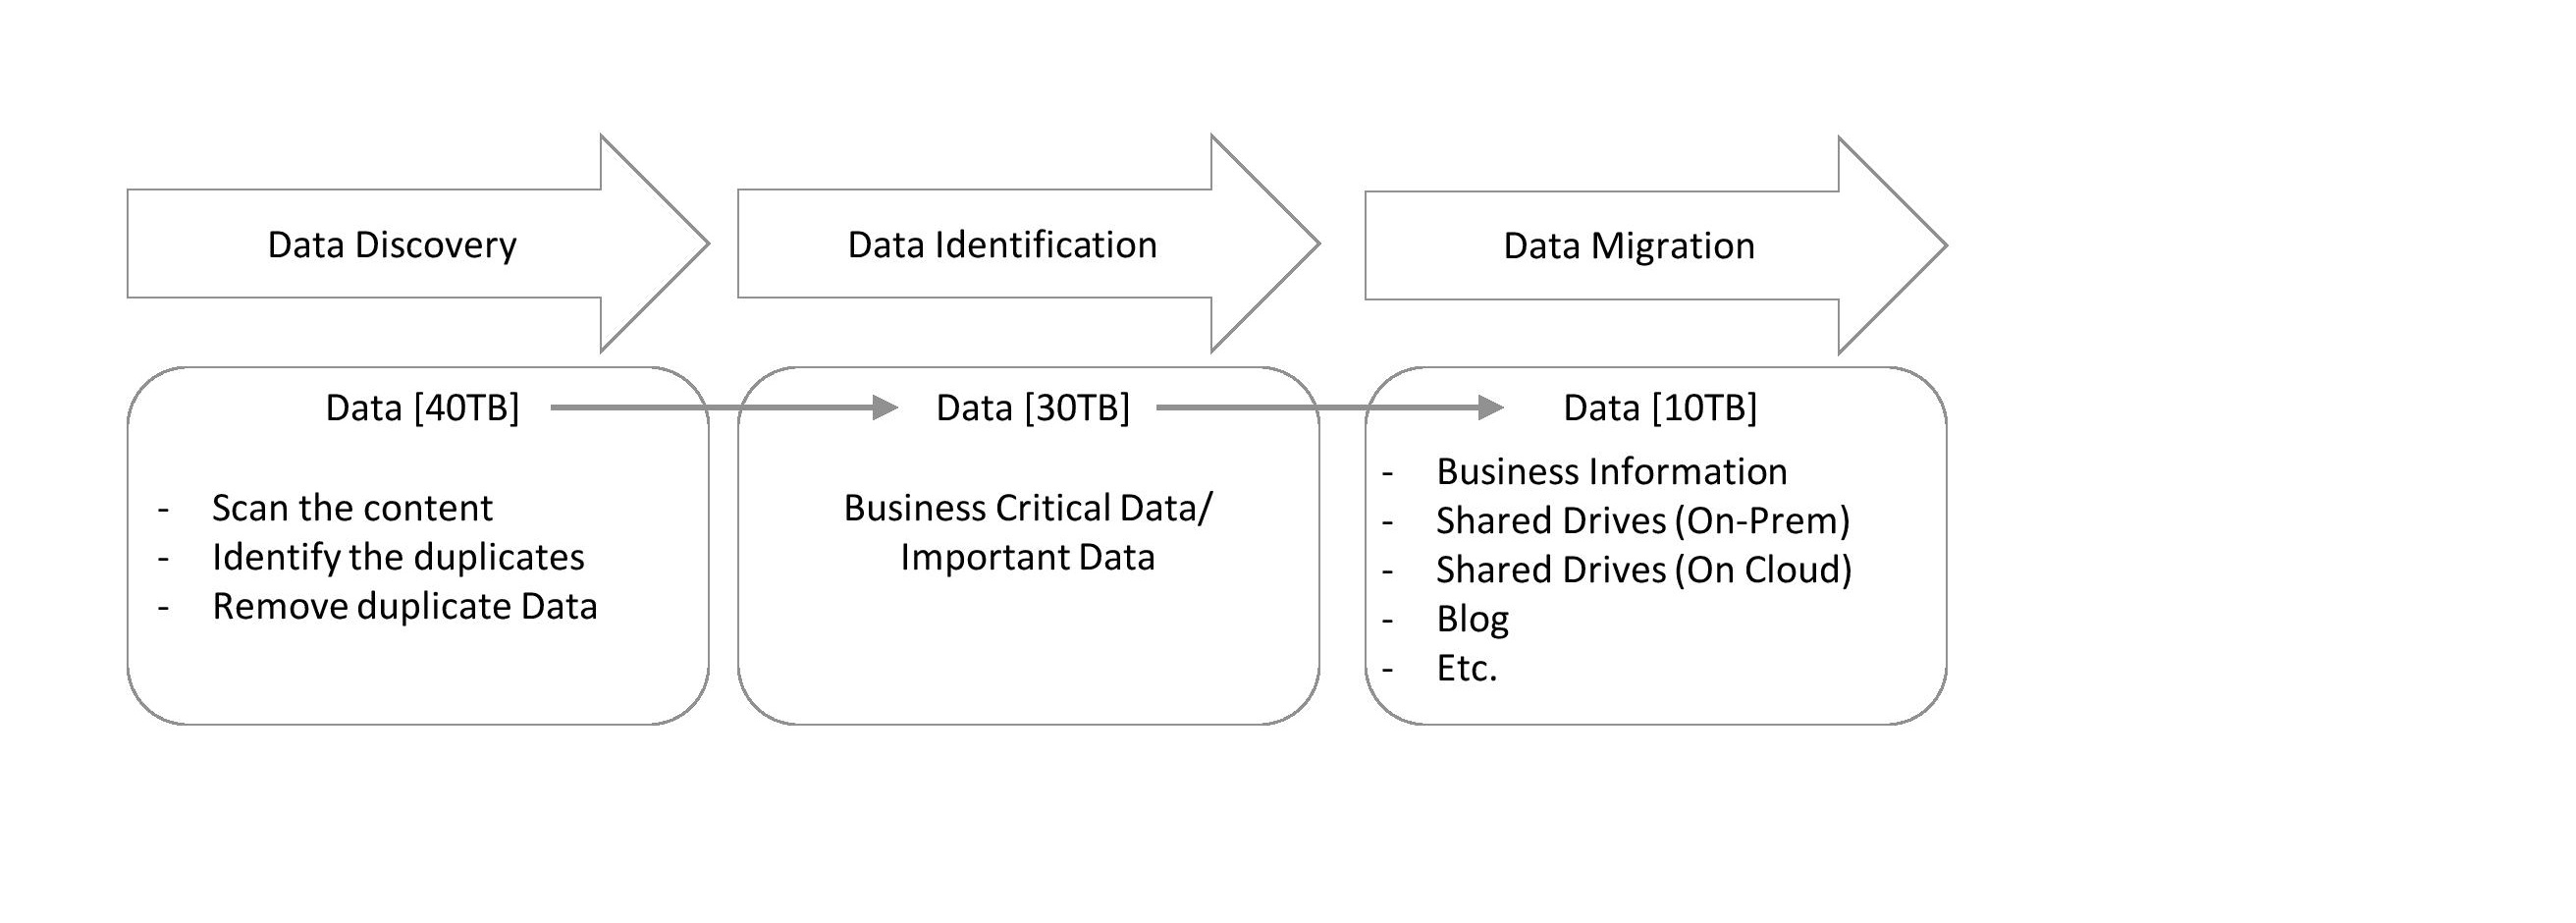
Data Identification is a very crucial exercise in data migration project where the process is to first conduct data discovery then data identification and then data migration can take place.
Data Identification can be done in all kinds of datasets i.e., structure, semi or unstructured but recommended practice is to do it in structured datasets.
Other Benefits
- Data dictionaries and data glossaries are also a good source for data identification.
- Data Anonymization becomes easy when Metadata Management is in place.
- Data Lineage also make life easy, to track where identified element has come from or where it will flow to.
- Data Identification also assists in conducting better Data Cleansing, Data Wrangling etc.
- With Data Identification, Data Quality implementation becomes highly achievable.
- While defining Golden Records during Master Data Management or defining Reference data, Data Identification also plays a vital role.
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.