Data Anonymization/Data Pseudonymization/Data De-Identification
From the book I Am Datapedia!, published here free by the author.
Data Anonymization, Data Pseudonymization or Data De-identification all worked the same way and related to Data Privacy.
Data Anonymization is about removing or modifying personal information before sharing with others so those people whom the data about remains anonymized.
‘Data Anonymization is about hiding the identity of a person to be undetectable.’
For example, while implementing a data solution it is required to share data with development team, so before sharing one must make sure data is anonymized, persons details are not exposed to development team members e.g., name, contact number, address, credit card number etc.
Data Anonymization is normally enforced by Regulatory Bodies and not following can result in heavy penalties and a bad reputation for any organization.
Techniques [All these terms are covered separately]
- Data Masking
- Data Pseudonymization
- Data Generalization
- Data Swapping
- Data Perturbation
- Data Synthetic
- Data Shuffling
- Data Scrambling
- Data Encoding
- Data De-identification
Disadvantages
- By anonymization, it can’t be used for marketing.
- Data Migration projects normally require original data set for testing so having anonymization can lead to mismatch of data.
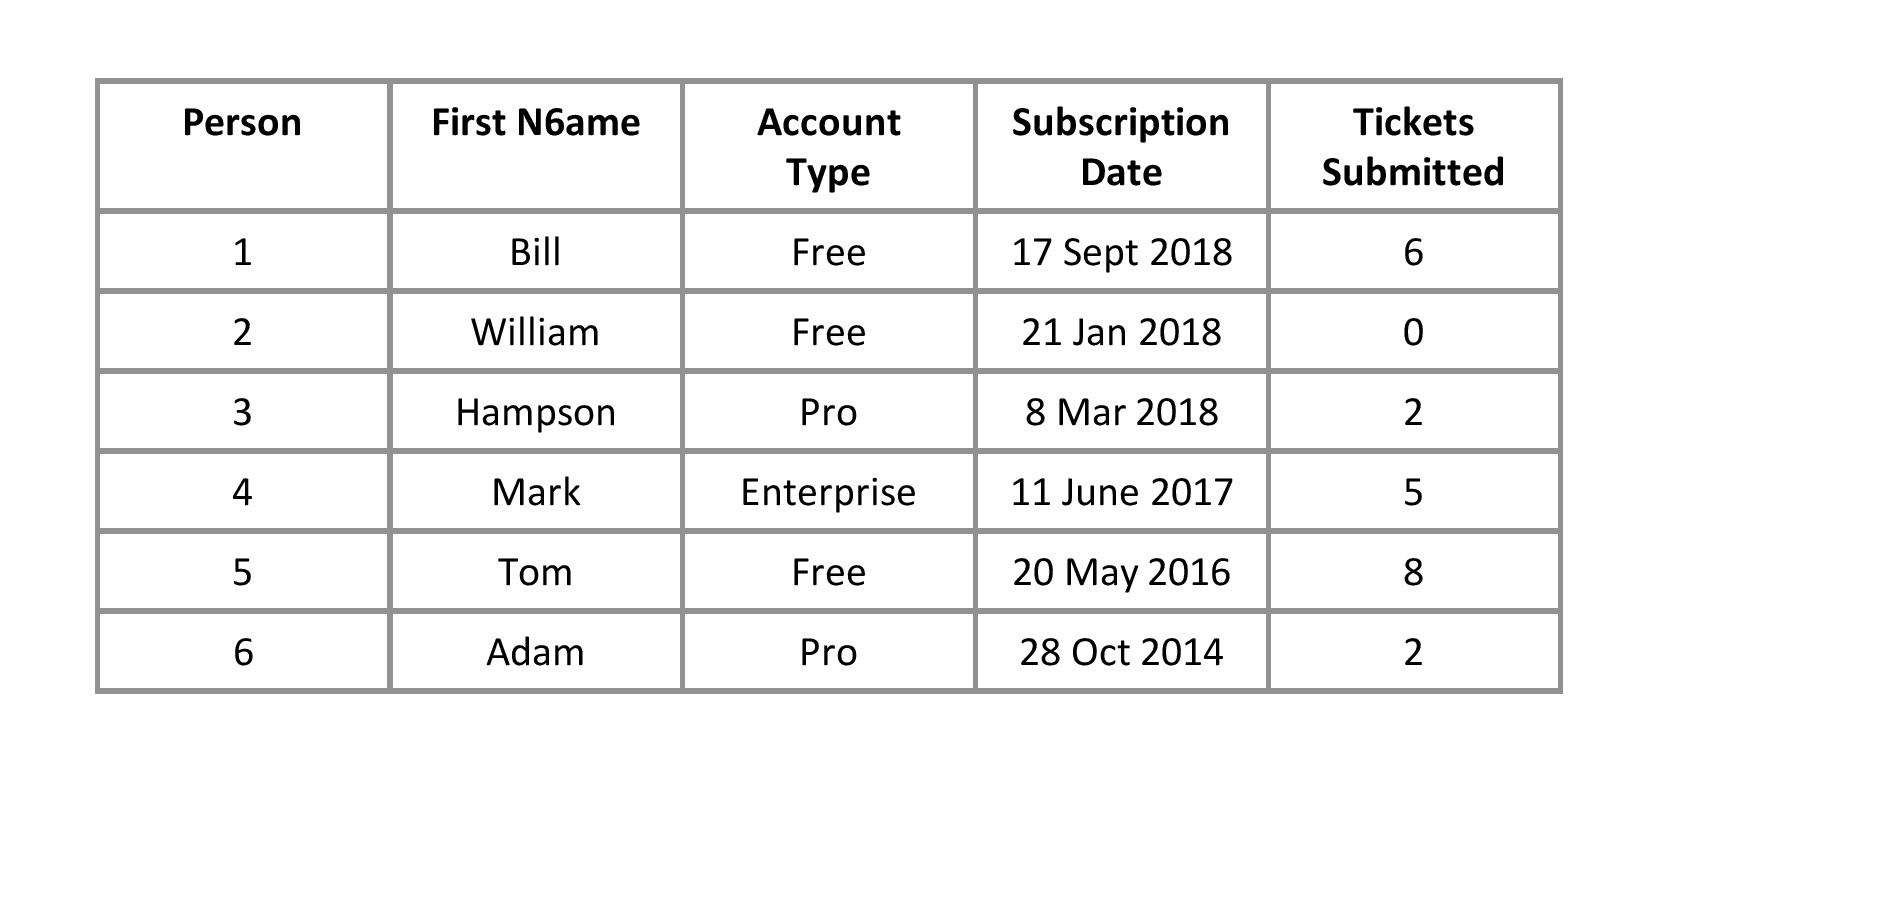
Below example of Data Anonymization is using Data Swapping technique.
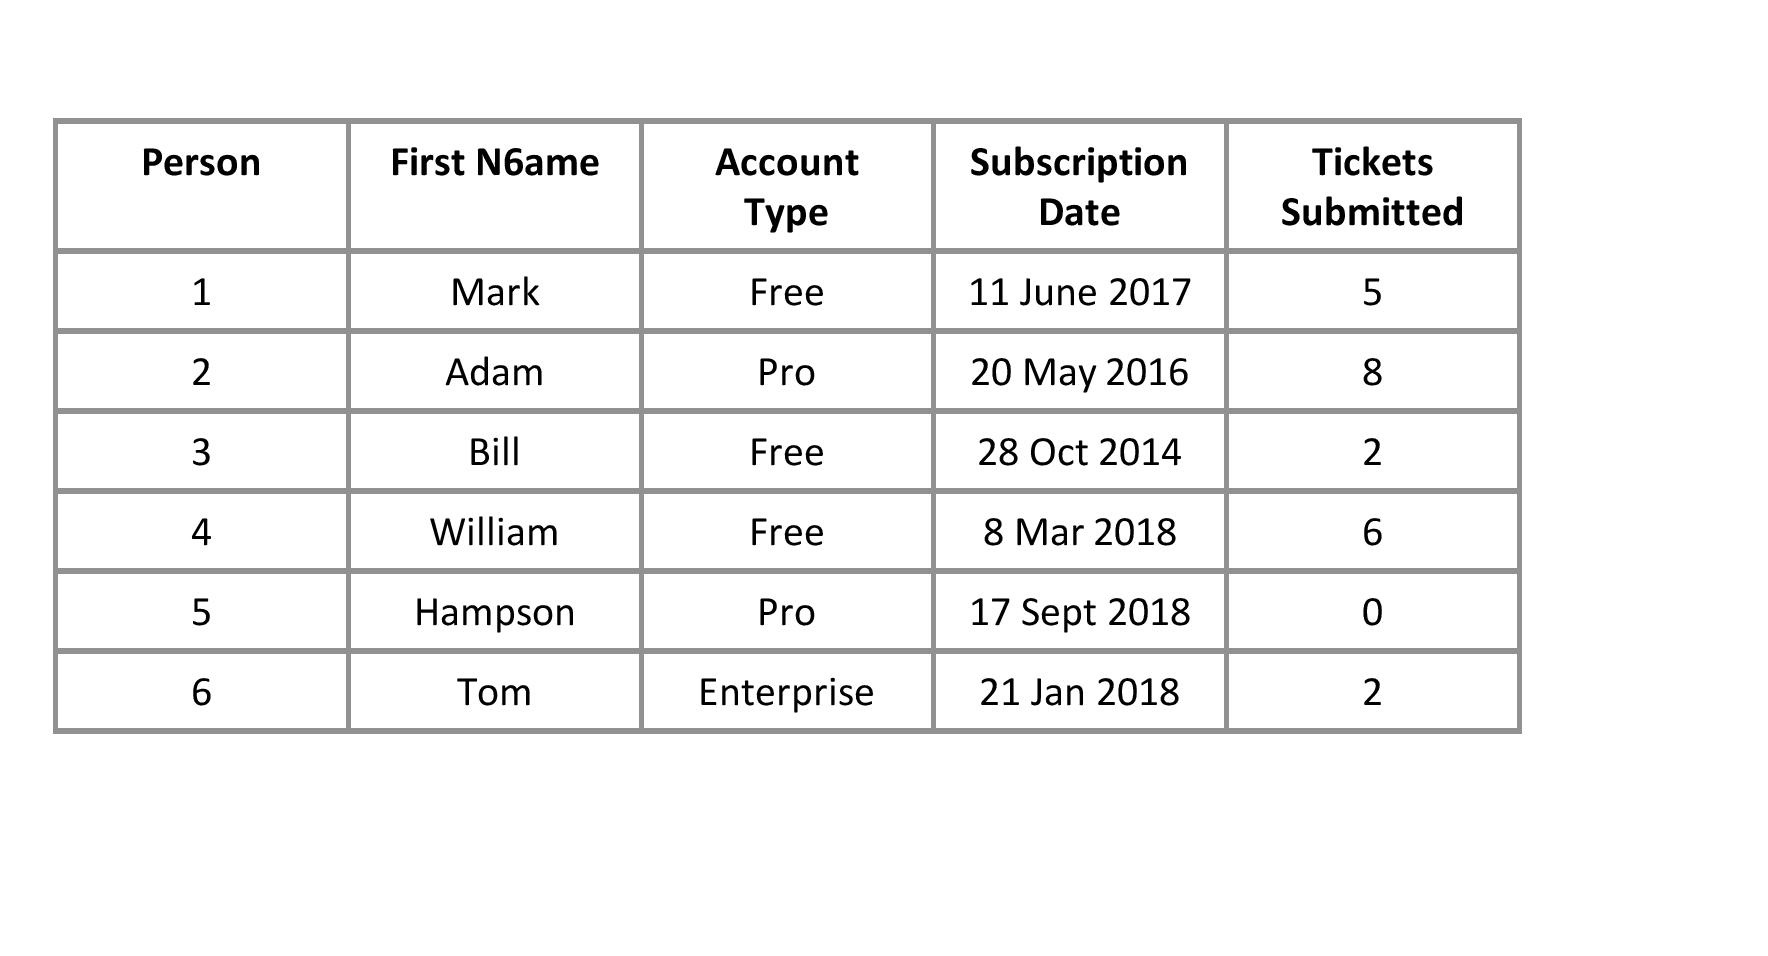
After Data Anonymization
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.