Learn free · topic 118
Data Perturbation/ Data Swapping/Data Shuffling/Data Scrambling/Data Obfuscation
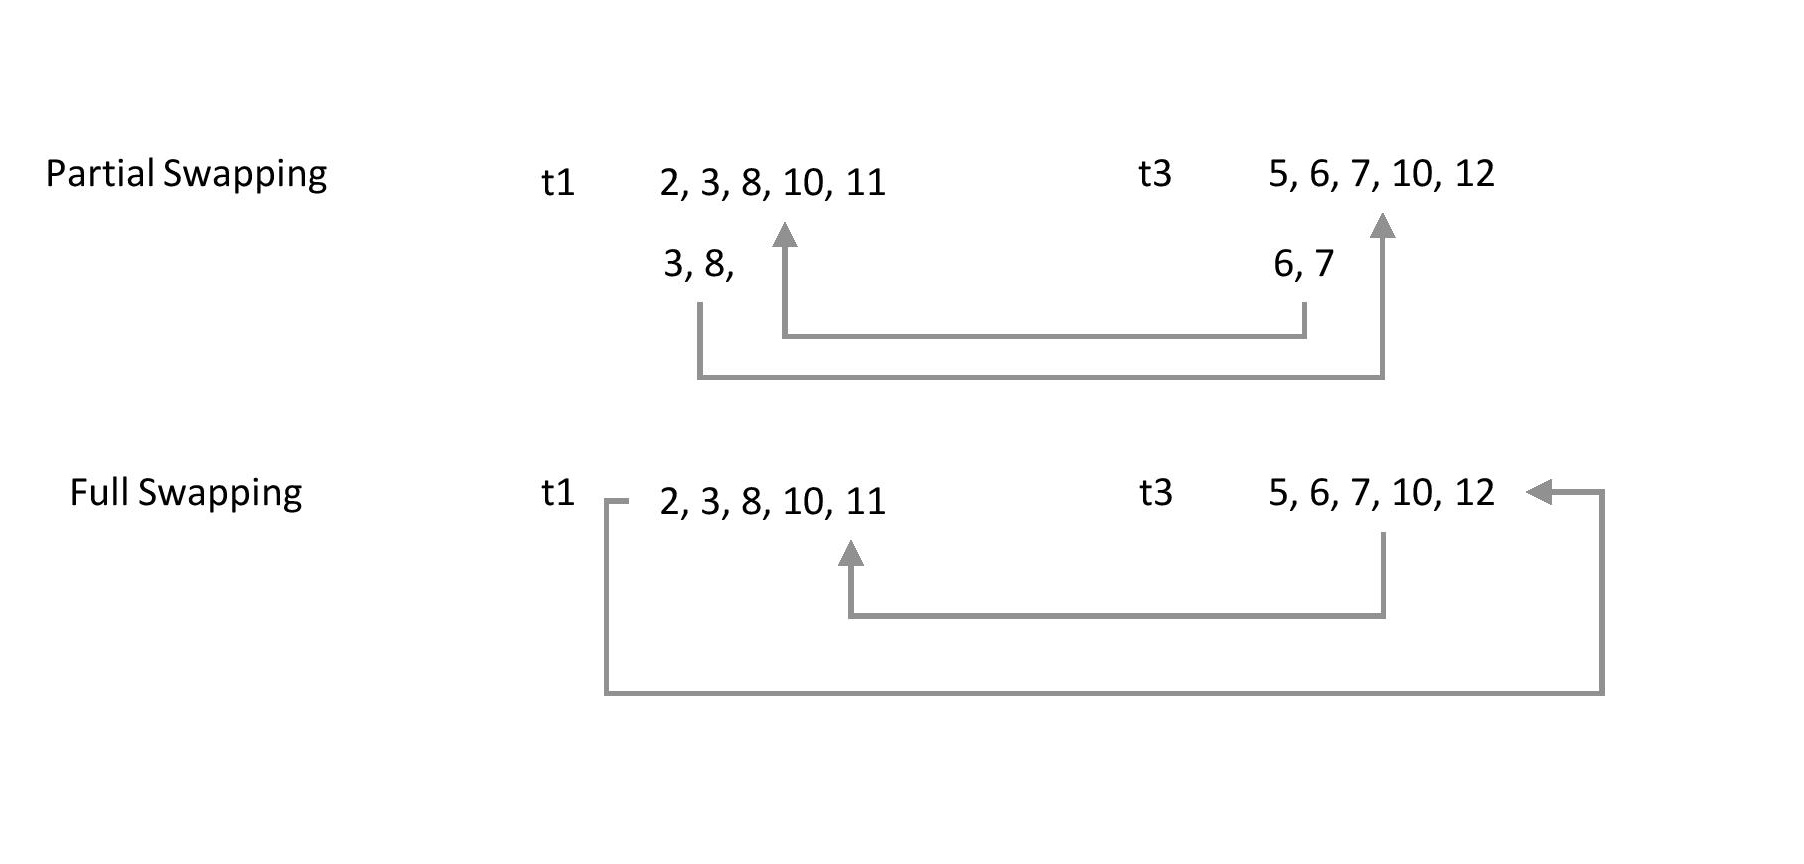
Data Swapping is about replacing the values of data at the same level of detail as compared to original data. In other words, cardinality (explained in a separate topic) of the replaced data is maintained.
- In Data Anonymization, identifiable data was removed.
- In Data Generalization, identifiable data is summarized.
- In Data Swapping, the level of identifiable data is replaced.
‘Data Swapping technique is majorly used by Data Scientists or Data Citizen who require data at the lowest level to create and train their Machine Learning Models.’
Let’s refer to the same Age example used in topic: Data Generalization/ Blurring and Specialization. For example, there can be an Age column with value: 26, 28, 31, 33, 37, 42, 42, 46, 48, 49, 54, 57, 57, 58, 59. In Data Swapping, to maintain the same level of detail i.e., ages can be swapped 26 with 59, 28 with 58, 32 with 57 and so on.
This way data is not changed at modelling normalization level or its not removed, or it not summarized in another column.
Type of Data Swapping
- Partial Swapping doesn’t replace all the value.
- Full Swapping replaces all the value.
‘Data Perturbation/ Swapping/ Shuffling/ Data Scrambling/ Data Obfuscation/ Data Masking all are permanent change of data and very had to revert rather most cases, are not reversible.’
Finished reading? Test yourself with 10 questions on this topic.
Go to the questions →From I Am Datapedia! by Mustafa Qizilbash, published here free by the author. Nothing about your reading is stored.