Data Imputation
From the book I Am Datapedia!, published here free by the author.
Data Imputation is majorly used in Data Science domain.
‘Imputation means, fill missing data.’
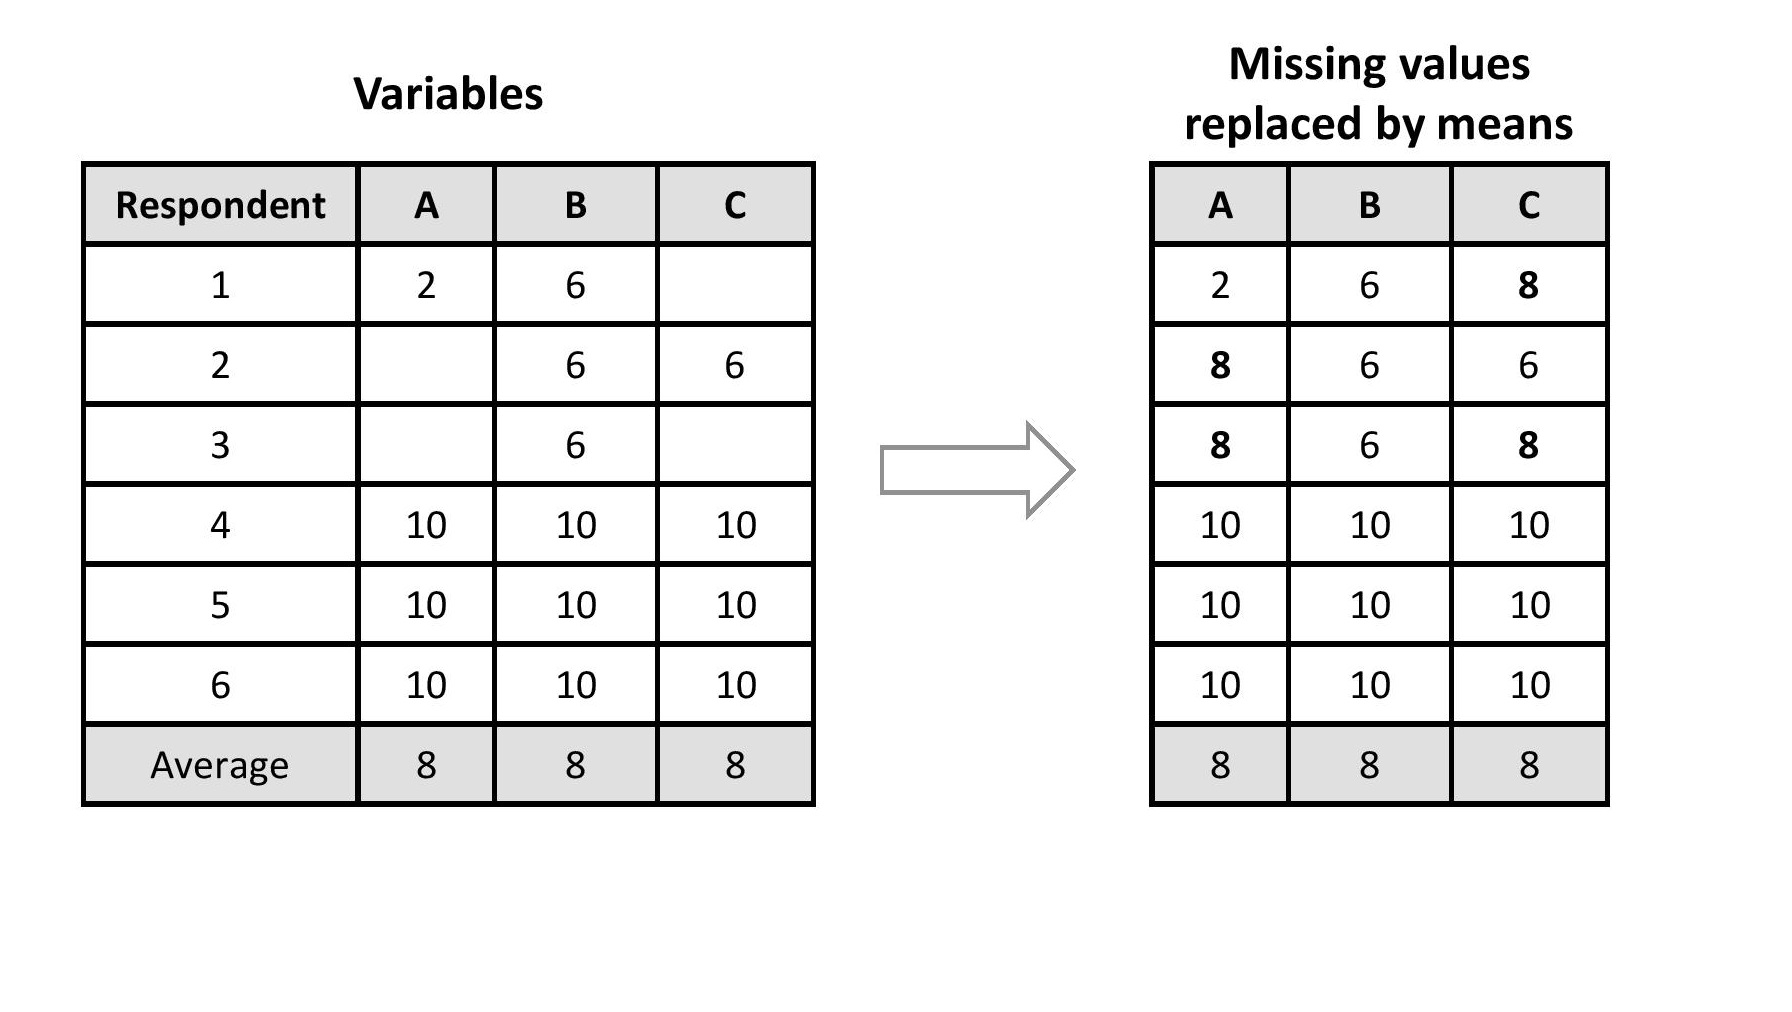
Missing value can create many kinds of issues e.g., during categorizing, classifying, clustering etc., if data is missing then results will not be 100%.
Generally, in numeric datasets, missing values are replaced with MEAN values. Having said that, there many ways to deal with missing data.
Few Imputations Techniques
- The first technique is where data is missing at random basis but before using it, it is completely removed from the dataset.
- The second technique is also where data is missing at random basis but here missing values are replaced referring to the other data points available with current dataset.
- Third technique is where data is not missing at random basis and mainly replaced using Mean/Median/Mode values.
Express your reaction
Your Take on This Insight?
Share how this content resonates with you.
0 reactionsSign in to react or comment
Comments (0)
No comments yet.
Free account
You can read every topic without one. A free account lets you react to this topic, comment under it and search the Knowledge Hub. Reacting and commenting need a confirmed e-mail address.