Learn free · topic 271
Data Backup and Mirroring
Data Backup and Mirroring are two terms that often cause confusion due to their similar nature, but they serve different purposes. Though both entail duplicating data, their goals differ. Let's delve into their distinctions.
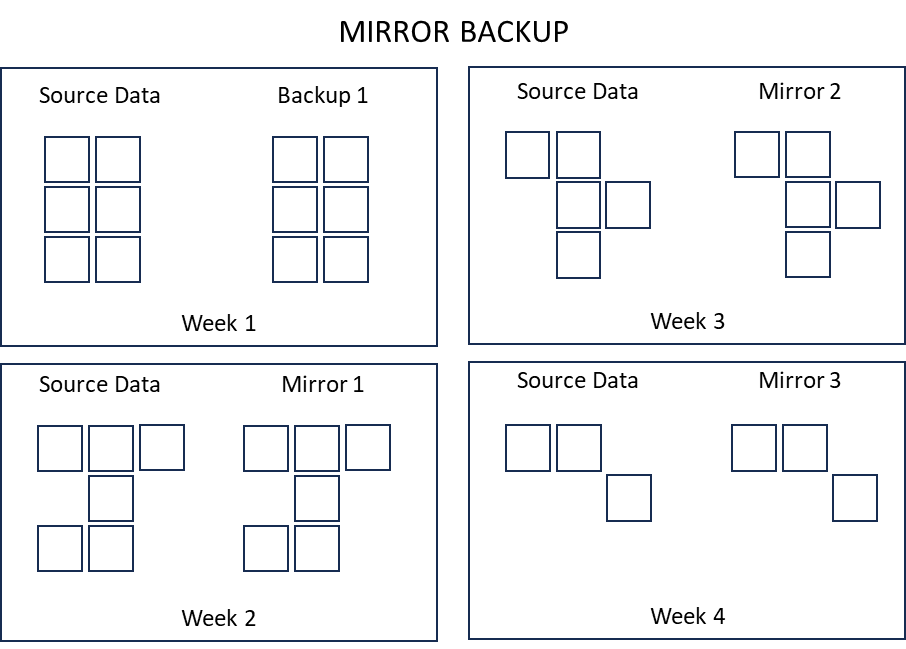
Data Backup:
The main purpose of data backup is to safeguard information for future use, regulatory adherence, or data retrieval in the event of loss. Many contemporary databases possess built-in backup capabilities. For instance, in the banking sector of certain countries, regulations stipulate retaining customer and associated data for a minimum of seven years after the customer departs from the bank. Data pertaining to active customers is kept indefinitely.
It is important to note that not all data is necessary for operational or reporting purposes. Decision support systems often demand particular data, housed within active databases such as OLTP (Online Transaction Processing) and OLAP (Online Analytical Processing). The remaining data is backed up using technologies such as tape drives or affordable storage solutions like Object Storage. Backups can be performed on a daily, weekly, monthly, quarterly, semi-annual, or annual basis, and various methods and techniques exist for taking backups.
Data Mirroring:
As previously stated, data mirroring operates akin to data backup, generating a replicated copy of data for future needs. However, the key distinction lies in the purpose of data mirroring, which is not long-term retention but rather establishing a starting point from which data can be mirrored.
For example, users can enable mirroring features on their laptops or systems, where the operating system periodically creates copies of data. In the event of data corruption due to bugs, viruses, or patches, one can restore the operating system and data from the mirrored copy, effectively reverting to a previous state.
Within the data domain, mirroring is also utilized for User Acceptance Testing (UAT), where an identical data replica is generated for business users to perform testing. Furthermore, if developers need particular datasets duplicated across various locations for diverse teams to use, they employ data mirroring.
It's worth noting that backups can be incremental, where only changes since the last backup are saved, while mirroring does not involve such incremental updates.
Finished reading? Test yourself with 10 questions on this topic.
Go to the questions →From I Am Datapedia! by Mustafa Qizilbash, published here free by the author. Nothing about your reading is stored.