Once you sign in, your details will show here.
Knowledge Hub
+ New Topic
Filter (2)
Sort
230 topics · Intermediate · I Am Datapedia! · 10 shown
Show allEvery topic is free to read. A free account also lets you search the topics, react to a topic and comment under it.
- I Am Datapedia!
Data Integration and Interoperability
Importance ofStaging Layer
Yes, you are right, in Data World, Staging Layer is one of the most important zones then why to write about it. Trust me it's been underutilized in most implementations.
Let's decode it.....
The Staging Layer in data architecture plays a crucial role in the data processing pipeline, providing a temporary and structured area for incoming data before it is integrated into the data warehouse or other storage systems.
Many a times Staging Layer is confused with Landing Layer. Yeah trust me, I have seen people doing nothing in Staging Layer except minor things. Please note, especially in the era of cloud, if one doesn’t properly utilize Staging Layer, the consumption cost from Staging Layer to Transformed Layer will be significantly higher.
The importance of the staging layer lies in several key aspects:
- Data Quality and Validation: The staging layer acts as a checkpoint for data quality and validation. Before data is moved to the main storage or processing area, it undergoes validation checks to ensure it meets quality standards. This helps identify and address issues such as missing values, formatting errors, or inconsistencies early in the data pipeline.
Data Enrichment: Staging allows for data enrichment processes to take place before the data reaches its final destination. This step involves cleaning, enhancing the data, making it more suitable for analysis and reporting. It ensures that the data conforms to the desired format and structure.
- Incremental Loading: The staging layer facilitates incremental loading of data, allowing for efficient updates and additions. Instead of reloading the entire dataset, only new or modified data needs to be processed, reducing the computational load and improving overall system performance.
- Data Auditing and Lineage: Staging provides a historical record of the ingested data, enabling auditing and tracing of changes over time. This is essential for tracking the lineage of data, understanding its origin, and ensuring compliance with data governance and regulatory requirements.
- Fault Tolerance and Recovery: Staging serves as a buffer against data processing failures. If an error occurs during data integration or transformation, the staging layer allows for easier recovery without affecting the main data storage. It provides a level of fault tolerance and helps maintain the integrity of the overall data processing pipeline.
- Isolation of Source and Destination Systems: Staging separates the source systems (where data originates) from the destination systems (where data is stored for analysis). This isolation ensures that any changes or issues in the source systems do not immediately impact the data warehouse or analytics environment, providing a layer of protection.
- Performance Optimization: By pre-processing and validating data in the staging layer, the main data storage systems are relieved of some of the computational overhead. This optimization contributes to improved performance and responsiveness in data processing.
3 min readMore
- I Am Datapedia!
Data Governance
GDPR
GDPR, or the General Data Protection Regulation, is a significant law in the European Union focused on data protection and privacy. In very simple terms, it's a set of rules about how companies and organizations should handle personal information of individuals. It gives people more control over their personal details like their names, addresses, and photos, ensuring that this information is handled in a secure and lawful manner.
The main principles of the GDPR center around responsible data management.
- Transparency is key, requiring clear communication about how personal data is used.
- Purpose limitation means data can only be used for specific, clearly stated reasons.
- Data minimization insists on collecting only the data that is absolutely necessary.
- The principle of accuracy ensures that personal information is kept up-to-date and correct.
- Storage limitation mandates that data should not be kept longer than necessary.
- Integrity and confidentiality require that the data is kept safe and secure, protected from unauthorized access or breaches.
- Accountability places the responsibility on organizations to ensure all these principles are adhered to, making sure personal data is managed in a compliant and ethical way.
4 min readMore
- I Am Datapedia!
Data Integration and Interoperability
ElectronicData Interchange (EDI)
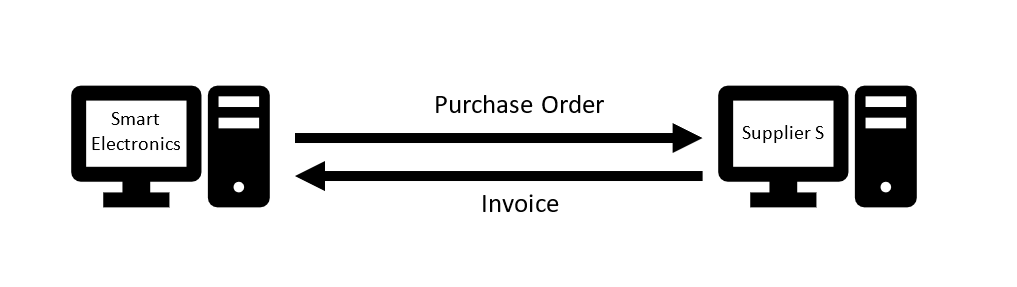
EDI, or Electronic Data Interchange has been introduced since the seventies. The main use case addressed by EDI is to automate data exchange between trading partners (Customers and Suppliers) for business documents, such as purchase orders and invoices as well as for payments and shipment information.
Here is a simple EDI use case in which Smart Electronics (a fictitious Manufacturing company) uses EDI to send Purchase Orders to Supplier S, and Supplier S sends corresponding invoices to Smart Electronics.
EDI follows specific message standards and formats like EDIFACT or X12 which are the main EDI message standards.
Other EDI standards have been developed for specific purposes or industries, such as:
- ODETTE: used in automotive industry in European countries
- HL7: used for healthcare data.
- IATA PATIS: used to exchange passenger and airport data, and is maintained by the IATA (the International Air Transport Association)
- SWIFT: used for transaction and message exchanges in the financial and banking sectors.
6 min readMore
- I Am Datapedia!
Data Warehousing and Business Intelligence
Attribution Data Models
Over the years, our approach to measuring marketing performance has drastically evolved and continues to change with advancing technology and evolving data policies. The days of rigidly assigning budgets to different marketing channels and relying solely on P&L statements to gauge the success of our efforts are behind us.
Assessing the performance of our ads involves understanding the correlation between our marketing spend and revenue generated. With data sources and clear models, especially when running campaigns across various channels simultaneously (e.g., Facebook, Google, Out Of Home, TV), the key question remains:
Which channels and touchpoints contribute significantly to the final sale?
To evaluate that, we employ distinct data models in marketing, each carrying its own set of advantages and limitations. These models must be tailored to fit each use case and align with how people interact with our business:
4 min readMore
- I Am Datapedia!
Data Warehousing and Business Intelligence
Incrementality inPerformance Marketing
Success in the dynamic landscape of marketing depends on engaging the right audience effectively. However, not all audiences respond the same to advertisements.
At the core of this lies a pivotal question:
Would customers buy without the corresponding paid advertising?
This question is at the core of incrementality in marketing, revealing three different ways people react to ads.Understanding Audience Behavior
This basic exploration breaks down how audiences react into three different groups:
- Non-responsive Audience: This group is unaffected by ads no matter how much they see them. They don't feel like engaging or buying because of ads.
- Pre-existing Demand Audience: People in this group were already planning to buy, ads or not. Ads might change when they buy, but they won't change their mind about buying.
- Incremental Audience: Importantly, this group includes people who are directly affected by ads. These potential customers engage or buy only because they saw ads, showing how much ads affect their behavior.
2 min readMore
- I Am Datapedia!
Data Storage and Operations
Materialized View orTemporary Tables in SQL
In typical SQL world (Structured Query Language), usually managing and manipulating data efficiently is very crucial for its performance, database lifecycle or DWH scalability. Temporary tables and materialized views are two powerful constructs (objects) that help in achieving both objectives simultaneously. Even though each serves a unique purpose within data operations and data streams. Let´s look at both little closer.
Temporary Tables
We can define them as typical tables which are created within a database session and are only available during the lifetime of that particular session. Lifetime during session is critical as they are designed to store intermediate results, results of window functions for complex calculations or data processing tasks and massive data manipulations.
Temporary tables are essentially useful in scenarios where data needs to be temporarily held and manipulated without affecting the main database tables. Here comes why it is called “temporary”. After your session ends, the temporary table is automatically discarded - same as you run command DROP TABLE, after query results are taken into another step. This way processing ensures no permanent database storage is consumed. You can imagine storing all 245 steps and their output tables consisting of 6 billion rows and 700 columns each day to have versions of each step.
3 min readMore
- I Am Datapedia!
Data Security
ISO/IEC 27001 fromData Perspective
During the years of industrialization and first process automations, there was the first batch of international standards which has become the core of ISO “framework”. When data stormed through various industries, ISO/IEC 27001 was necessary to be defined. It is an international standard specifying the requirements for establishing, implementing, maintaining, and continually improving an information security management system (ISMS). From a data perspective, this standard is core, essentially pivotal to ensure the confidentiality, integrity, and availability (CIA) of data. It consists of 3 main sections, which encompasses policies, processes, and technical measures to manage information security risks.
There are 6 Key Components when dealing with data and data management.
- The foundational aspect for ISO/IEC 27001 is the systematic assessment of information security risks in your own data. Risk assessment includes identifying potential threats to data, assessing vulnerabilities, and risk impacts’ evaluation. The outcome guides the prioritization of security processes, monitoring and controls.
- Managing risk effectively, data must be classified according to its sensitivity and importance to the organization and its departments. Such classification influences how data is handled, stored, and transmitted, ensuring that more sensitive data receives higher levels of protection. The processing phase is called data classification.
- ISO/IEC 27001 highlights massive importance for limiting access to data based on the principle of least privilege. Access control lineage and its measures ensure that only authorized individuals can access or modify data, reducing the risk of unauthorized disclosure, alteration, partial loss, or total destruction.
- Encrypting data (both at rest and in transit], is a very common control in data protection process for keeping confidentiality and integrity. Encryption makes data unreadable to unauthorized parties, safeguarding it against spying or undesired interfering.
- Next component the ISO standard 27001 requires for all organizations to have procedures for managing information security incidents. Incident Management includes detecting, reporting, and investigating each incident to mitigate their impact on data and prevent recurrence.
- Last but not least ISO/IEC 27001 brought into place Business Continuity Management to keep development of any business continuity plan which includes data recovery procedures. “Continuity” ensures that critical data remains available or can be restored in the event of a disruption. Under “event” you can imagine a typical cyber-attack or natural disaster.
4 min readMore
- I Am Datapedia!
Data Governance
ILM – InformationLifecycle Management
Let’s start by breaking down each part of this acronym based on the context of its usage.
- Information – In this case the Information is related to the usage of the related data stored in a database or a data platform.
- Lifecycle – The standard definition for life cycle is the different stages of life for a living thing. In this case the living thing is the Data. The Lifecycle for data is classified based on its usage as: - ‘HOT’, ‘WARM’, ‘COLD’ and that also could be extended to ‘DEAD’ for deleted.
- Management – The process to facilitate the movement of the data related to the information over its Lifecycle.
So, using the context above, Information Lifecycle Management (ILM) is the process to optimize data storage by automatically tiering data to different locations based on its age, access frequency, and required read/write speeds. This approach minimizes storage costs by placing frequently accessed data in high-performance tiers and infrequently accessed or archived data in lower-cost tiers. ILM can also simplify data archiving and deletion according to data retention policies.
7 min readMore
- I Am Datapedia!
Data Architecture
Reference Architecture
Reference Architecture is foundational to designing any complex system or solution. It provides a high-level diagram that represents the structural pattern of the solution, establishing a consistent framework that guides the design and implementation of similar projects across an organization. Unlike solution architecture, which is customized for each project, reference architecture offers a generalized template that aligns with established best practices, making it broadly applicable and easily understandable for both technical and non-technical stakeholders.
Purpose and Benefits
The main objective of a reference architecture is to set a standardized approach for designing solutions within an organization. This ensures consistency, reduces redundancy, and accelerates solution delivery by offering a clear blueprint. With this architecture, teams can quickly understand the fundamental elements of the solution, enabling efficient alignment with organizational goals. Additionally, reference architectures aid in risk management by promoting tried-and-tested design patterns and technologies, minimizing potential errors in execution.
4 min readMore
- I Am Datapedia!
Data Architecture
Data Product
Before we explore what constitutes a Data Product (DP), it is important to establish the foundational context within which these products exist. Most enterprise data environments comprise two distinct but interconnected types of systems:
- OLTP (Online Transaction Processing) systems, which are responsible for generating operational data through transactional processes.
- OLAP (Online Analytical Processing) systems, which are designed to serve data for analytical and decision-support purposes.
We will not dive into the technical specifics of OLTP and OLAP here, as those are covered in dedicated sections elsewhere in this book. However, it is essential to understand this distinction because Data Products are primarily built and operated within the OLAP ecosystem.
In essence, OLTP generates data. OLAP serves it.
Data products are almost always born, shaped, and consumed in the OLAP layer, where raw data is transformed into meaningful, trustworthy outputs for business consumption.
4 min readMore
Build a strong foundation in Data & AI
Follow the Data Foundations learning path (Beginner to Advanced).