Once you sign in, your details will show here.
Knowledge Hub
+ New Topic
Filter (1)
Sort
230 topics · Intermediate · 10 shown
Show allEvery topic is free to read. A free account also lets you search the topics, react to a topic and comment under it.
- I Am Datapedia!
AI and Machine Learning
Entity Recognition
Entity Recognition, commonly known as Named Entity Recognition (NER), is a technique used to identify and extract meaningful entities from unstructured text. It is also referred to as entity identification or entity extraction. While entity recognition has long been appreciated in data modeling, particularly during conceptual modeling when identifying core business entities, it plays an equally critical role in the data science domain.
In traditional structured systems, entities such as Customer, Product, Order, or Invoice are clearly defined within database schemas. However, modern organizations generate enormous volumes of unstructured data from social media posts, emails, PDF files, Word documents, comment columns, chat transcripts, and even video or audio content converted into JSON or text formats. For data modelers, this unstructured layer represents one of the greatest challenges when designing robust data models.
4 min readMore
- I Am Datapedia!
AI and Machine Learning
Causality Data
Causality Data in the data world refers to information that helps establish a cause-and-effect relationship between different variables or events. In other words, it involves understanding the influence or impact that changes in one variable have on another.
Causality is a fundamental concept in statistics and data analysis, especially when trying to make sense of complex systems or phenomena. Establishing causal relationships is important for drawing meaningful conclusions and making informed decisions. However, it is essential to word that correlation does now no longer imply causation. While two variables may be correlated, it doesn't necessarily mean that one causes the other.
In the context of data science and analytics, establishing causality often involves advanced statistical methods and experimentation.
Here are a few key points related to causality data:
- Experimental Design: Controlled experiments, where researchers manipulate one variable while keeping others constant, are often used to establish causality. This allows for the isolation of the variable of interest and helps draw conclusions about its impact.
- Observational Studies: In cases where controlled experiments are not feasible, observational studies are conducted to analyze existing data. However, establishing causality in observational studies can be more challenging due to potential confounding factors.
- Counterfactuals: Causality often involves comparing what happened to what might have happened in the absence of a particular intervention or change. This comparison is known as a counterfactual analysis.
- Temporal Order: Causality requires that the cause precedes the effect in time. Observing a temporal order between variables is an important aspect of establishing causation.
- Statistical Techniques: Various statistical techniques, such as regression analysis, propensity score matching, and instrumental variable analysis, are employed to analyze data and infer causal relationships.
4 min readMore
- I Am Datapedia!
AI and Machine Learning
Inference Data
Inference Data refers to the data produced by ML process of drawing conclusions, making predictions, or generalizing information based on the analysis of a features dataset. It is a crucial step in extracting meaningful insights from data and often involves the application of statistical methods.
Let's decode it.....
Imagine you want to know something about a big group of students, like all the students in your school. Instead of asking every single student (which could be too much work), you ask a smaller group. This smaller group is like a sample. In simpler terms, inference is like making smart guesses about everyone by looking at a few representative friends first. It's a bit like saying, "I can figure out what most people like, by asking a few of them because they're probably a lot like everyone else."
Inference data is a process of drawing meaningful conclusions about a larger dataset based on observed data, and it is a fundamental aspect of statistical reasoning and data analysis in various domains.
2 min readMore
- I Am Datapedia!
Reference and Master Data
Master andReference Data Management
If you would like to step into the data domain, the most significant topics anybody must recognize are Metadata, Master & Reference Data Management. If you grasp these areas, one will require 80% less time to orchestrate any Data Solution.
Master Data refers to the core datasets that are essential for business operations and act as the foundation for all other data within an organization. These datasets typically represent key entities or subjects that are critical to the functioning of the business and are used across multiple systems, processes, or applications.
A unique characteristic of Master Data is that it cannot exist independently, it relies on the existence of specific entities or attributes to be meaningful. For example, you cannot have a customer master record without defining key attributes such as the customer’s name, address, and unique identifier (e.g., customer ID). Similarly, a product master record cannot be created without information such as the product name, SKU, or category.
6 min readMore
- I Am Datapedia!
Metadata
Metadata Management
Metadata Strategy should take place along with project or product strategies, means the earlier the better.
We stated in the Master Data Management term, can Metadata & Master Data reduce your BI footprint by 80%? Yes, it can. For example, if you produce a dashboard/report and describe its Metadata in such a manner that it articulates the entire story around the data points and the KPIs in it then the next BI report will only be generated if the earlier one doesn’t aid the purpose.
In a generic sense we say, Metadata is moreover Data-About-Data, but Metadata is beyond Data-About-Data. It can tell you about business requirements, it can tell you about business goals, it can tell you about Business KPIs etc.
We all have read books either in our student lives or professionally. The Index of the book is Metadata which indicates which page contains which topic. The Acknowledgment page of the book is Metadata as well which tells the overall background, reason, agenda etc., about the book. Metadata can host roles, grants, business processes, terms and conditions, data points and KPI(s) on dashboards and reports, details about databases, tables, columns and rows, the definition of the tables, description of the columns etc. If your Metadata is not in place, you can’t figure out Data Lineage. If your Data Lineage is not placed, your Data will become a Data Swamp, so on…. And again, you are expendable☺. Now is the era of Big Data and Data Lakes, social media, and semi and unstructured data. If one builds a Data Lake without Metadata Management in place, good luck to the organization.
4 min readMore
- I Am Datapedia!
Metadata
Active Metadata
Metadata Management is one of the key components of Data Strategy and Data Management. Is Metadata and Active Metadata two different things. ACTUALLY NO.
Let’s decode it…..
Active Metadata is a new term or jargon surfacing now a days but in-reality, there is no difference between traditional/ passive and active Metadata. Having said that there is difference between how active and passive metadata are generated and managed.
As the name says it all, active metadata is generated automatically and continuously by systems or tools and used to systems approaches like Data Fabric (explained in separate topic).
Data Fabric is the BRAIN where-as, rest of the data components are parts of body in a data solution. BRAIN needs continuous input, BRAIN needs to know everything at the right time rather all the time, dynamically.
1 min readMore
- I Am Datapedia!
Metadata
How to SelectYour Metadata
While the objective is to imbue data with context, the crucial question is: what type of context are we seeking? Ideally, we aim for a trustworthy and secure context.
Outlined below are 3 high-level steps to guide you in selecting mandatory metadata effectively.
- Choosing the Right Metadata using the 5W 1H Method: Employ the 5W 1H method (Who, What, When, Where, Why, and How) to meticulously choose metadata that aligns with your specific objectives. This method ensures a comprehensive understanding of the context each metadata element provides.
- Filtering the metadata with 3 Selection Criteria: Streamline your selection further by applying three essential criteria to the metadata options:
- For Everyone: Choose metadata that anyone can understand, not tied to specific organizations or industries. This makes data easy to use, keeps it relevant, and encourages more people to get involved.
- Anyone Can Create: Pick metadata that anyone familiar with the organization's data can create. No need for technical or legal expertise. This makes the process open to everyone, speeds things up, and promotes collaboration.
- Follow Standards: Ensure your metadata follows universal standards. This keeps things consistent internally and aligns with best practices in the industry, making it easy to share data with others.
3 min readMore
- I Am Datapedia!
Data Modeling and Design
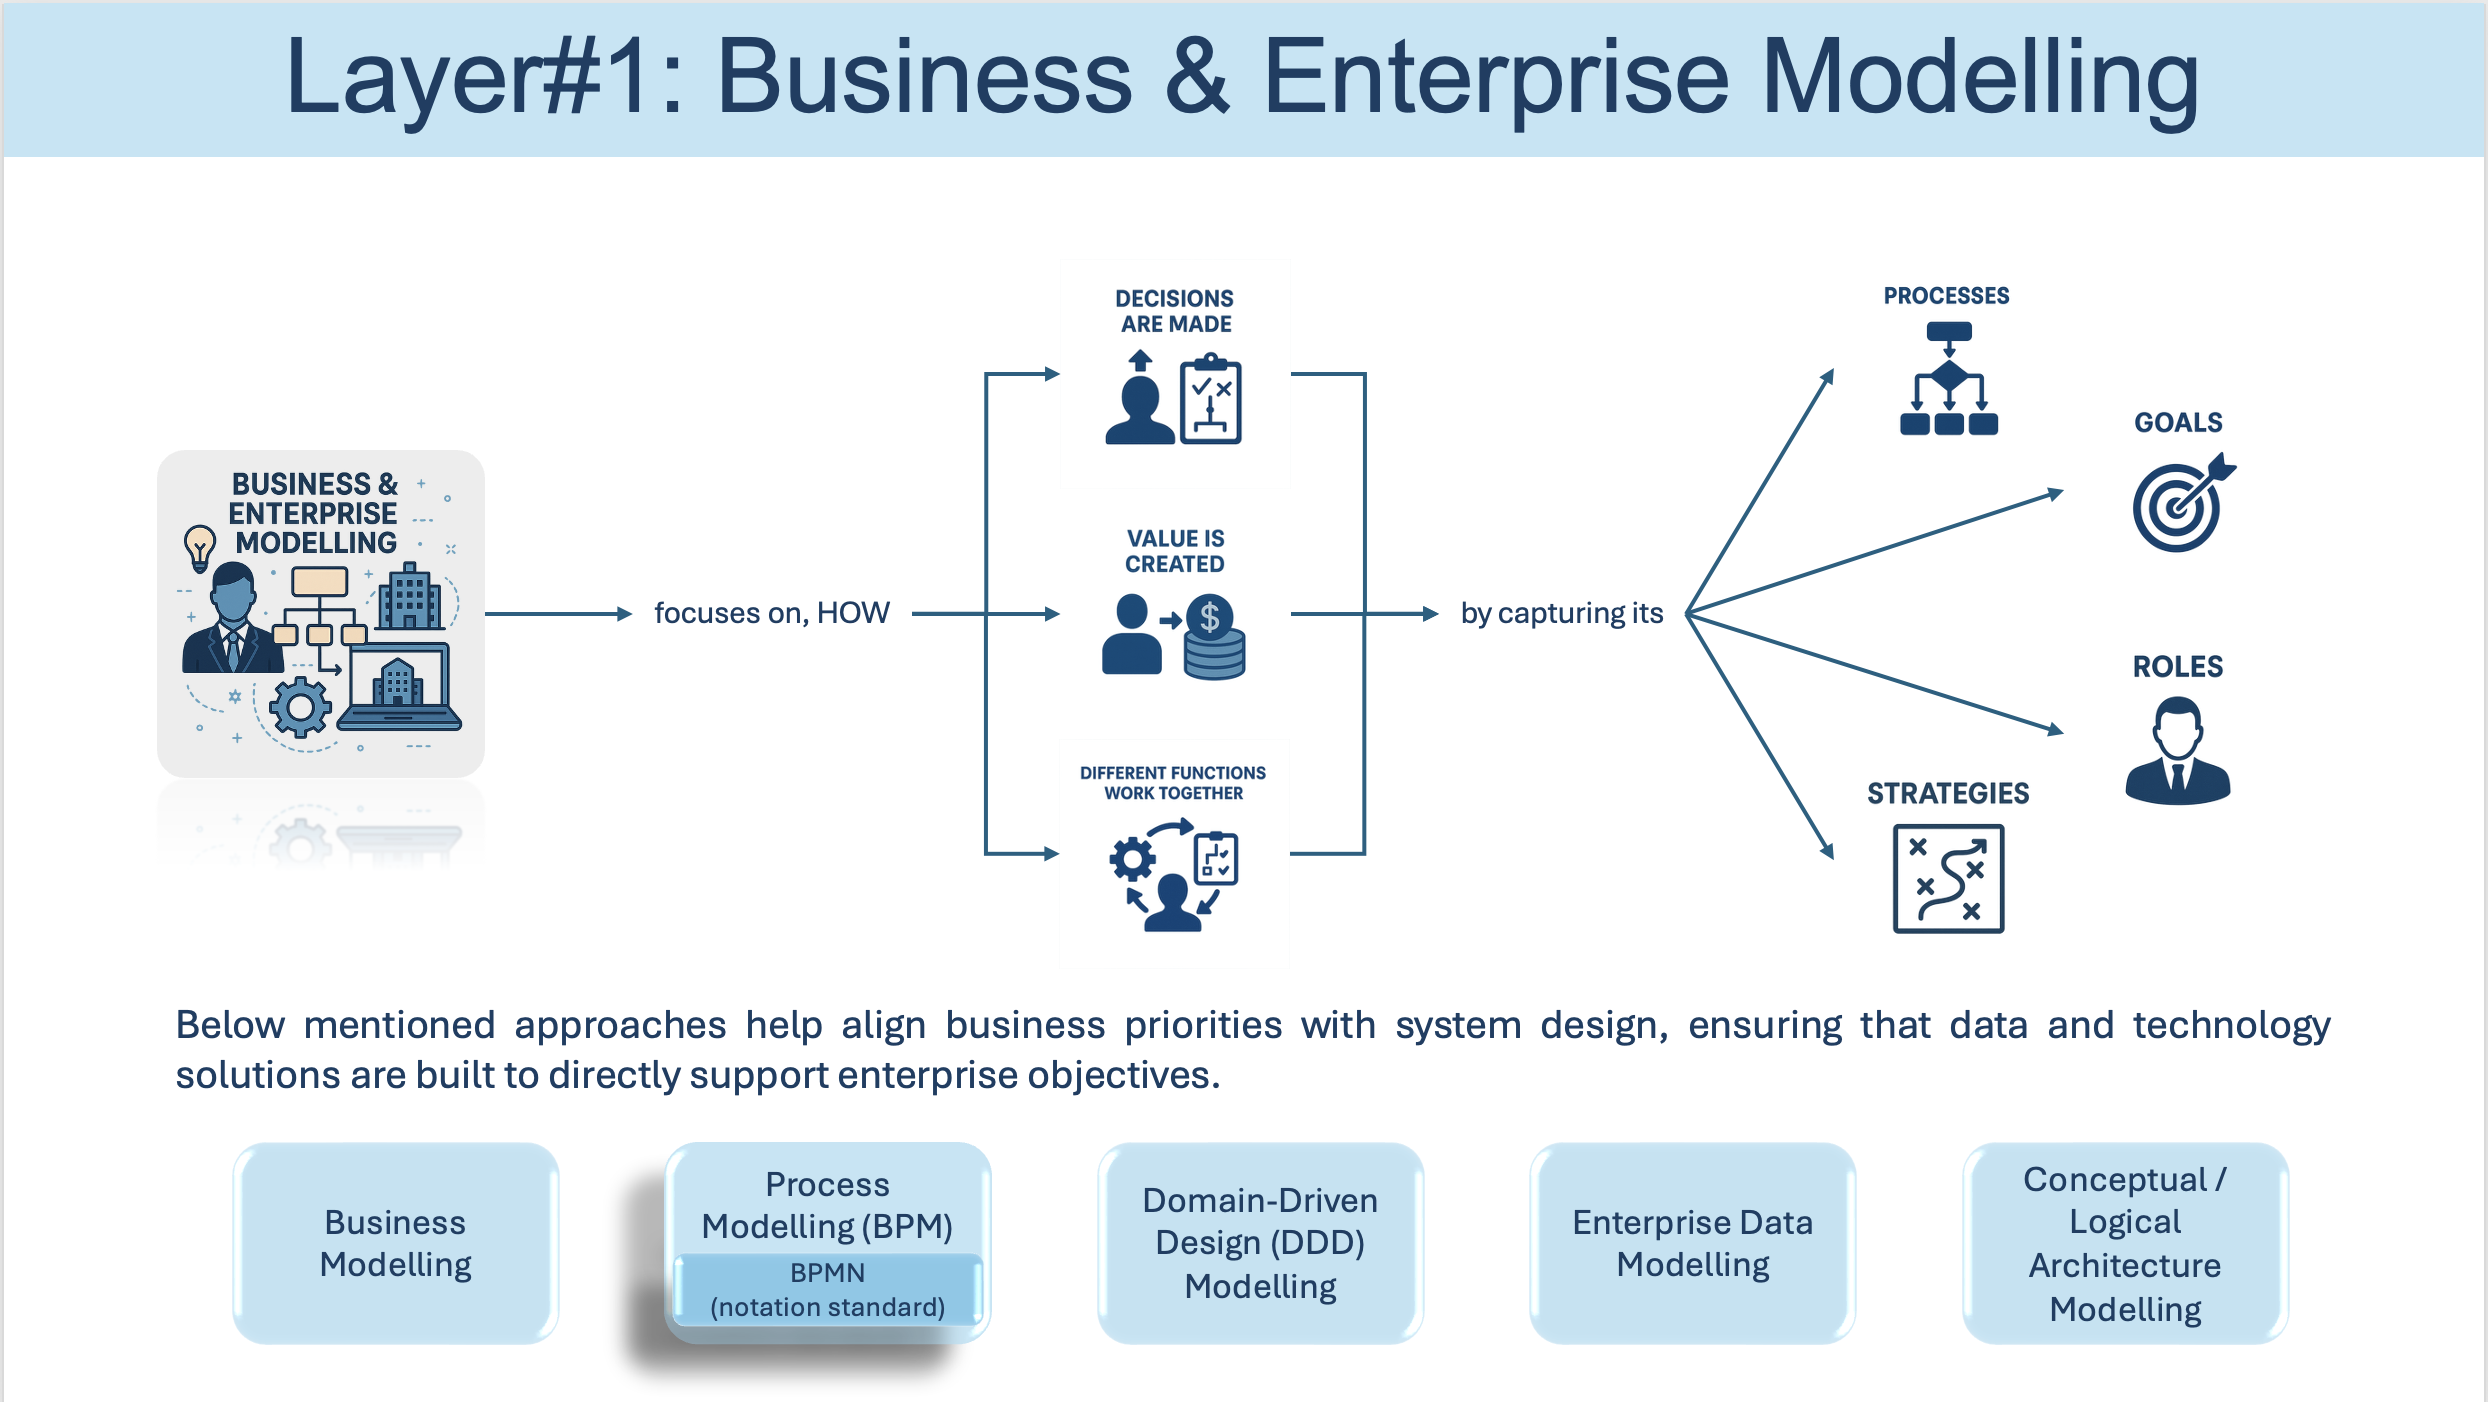
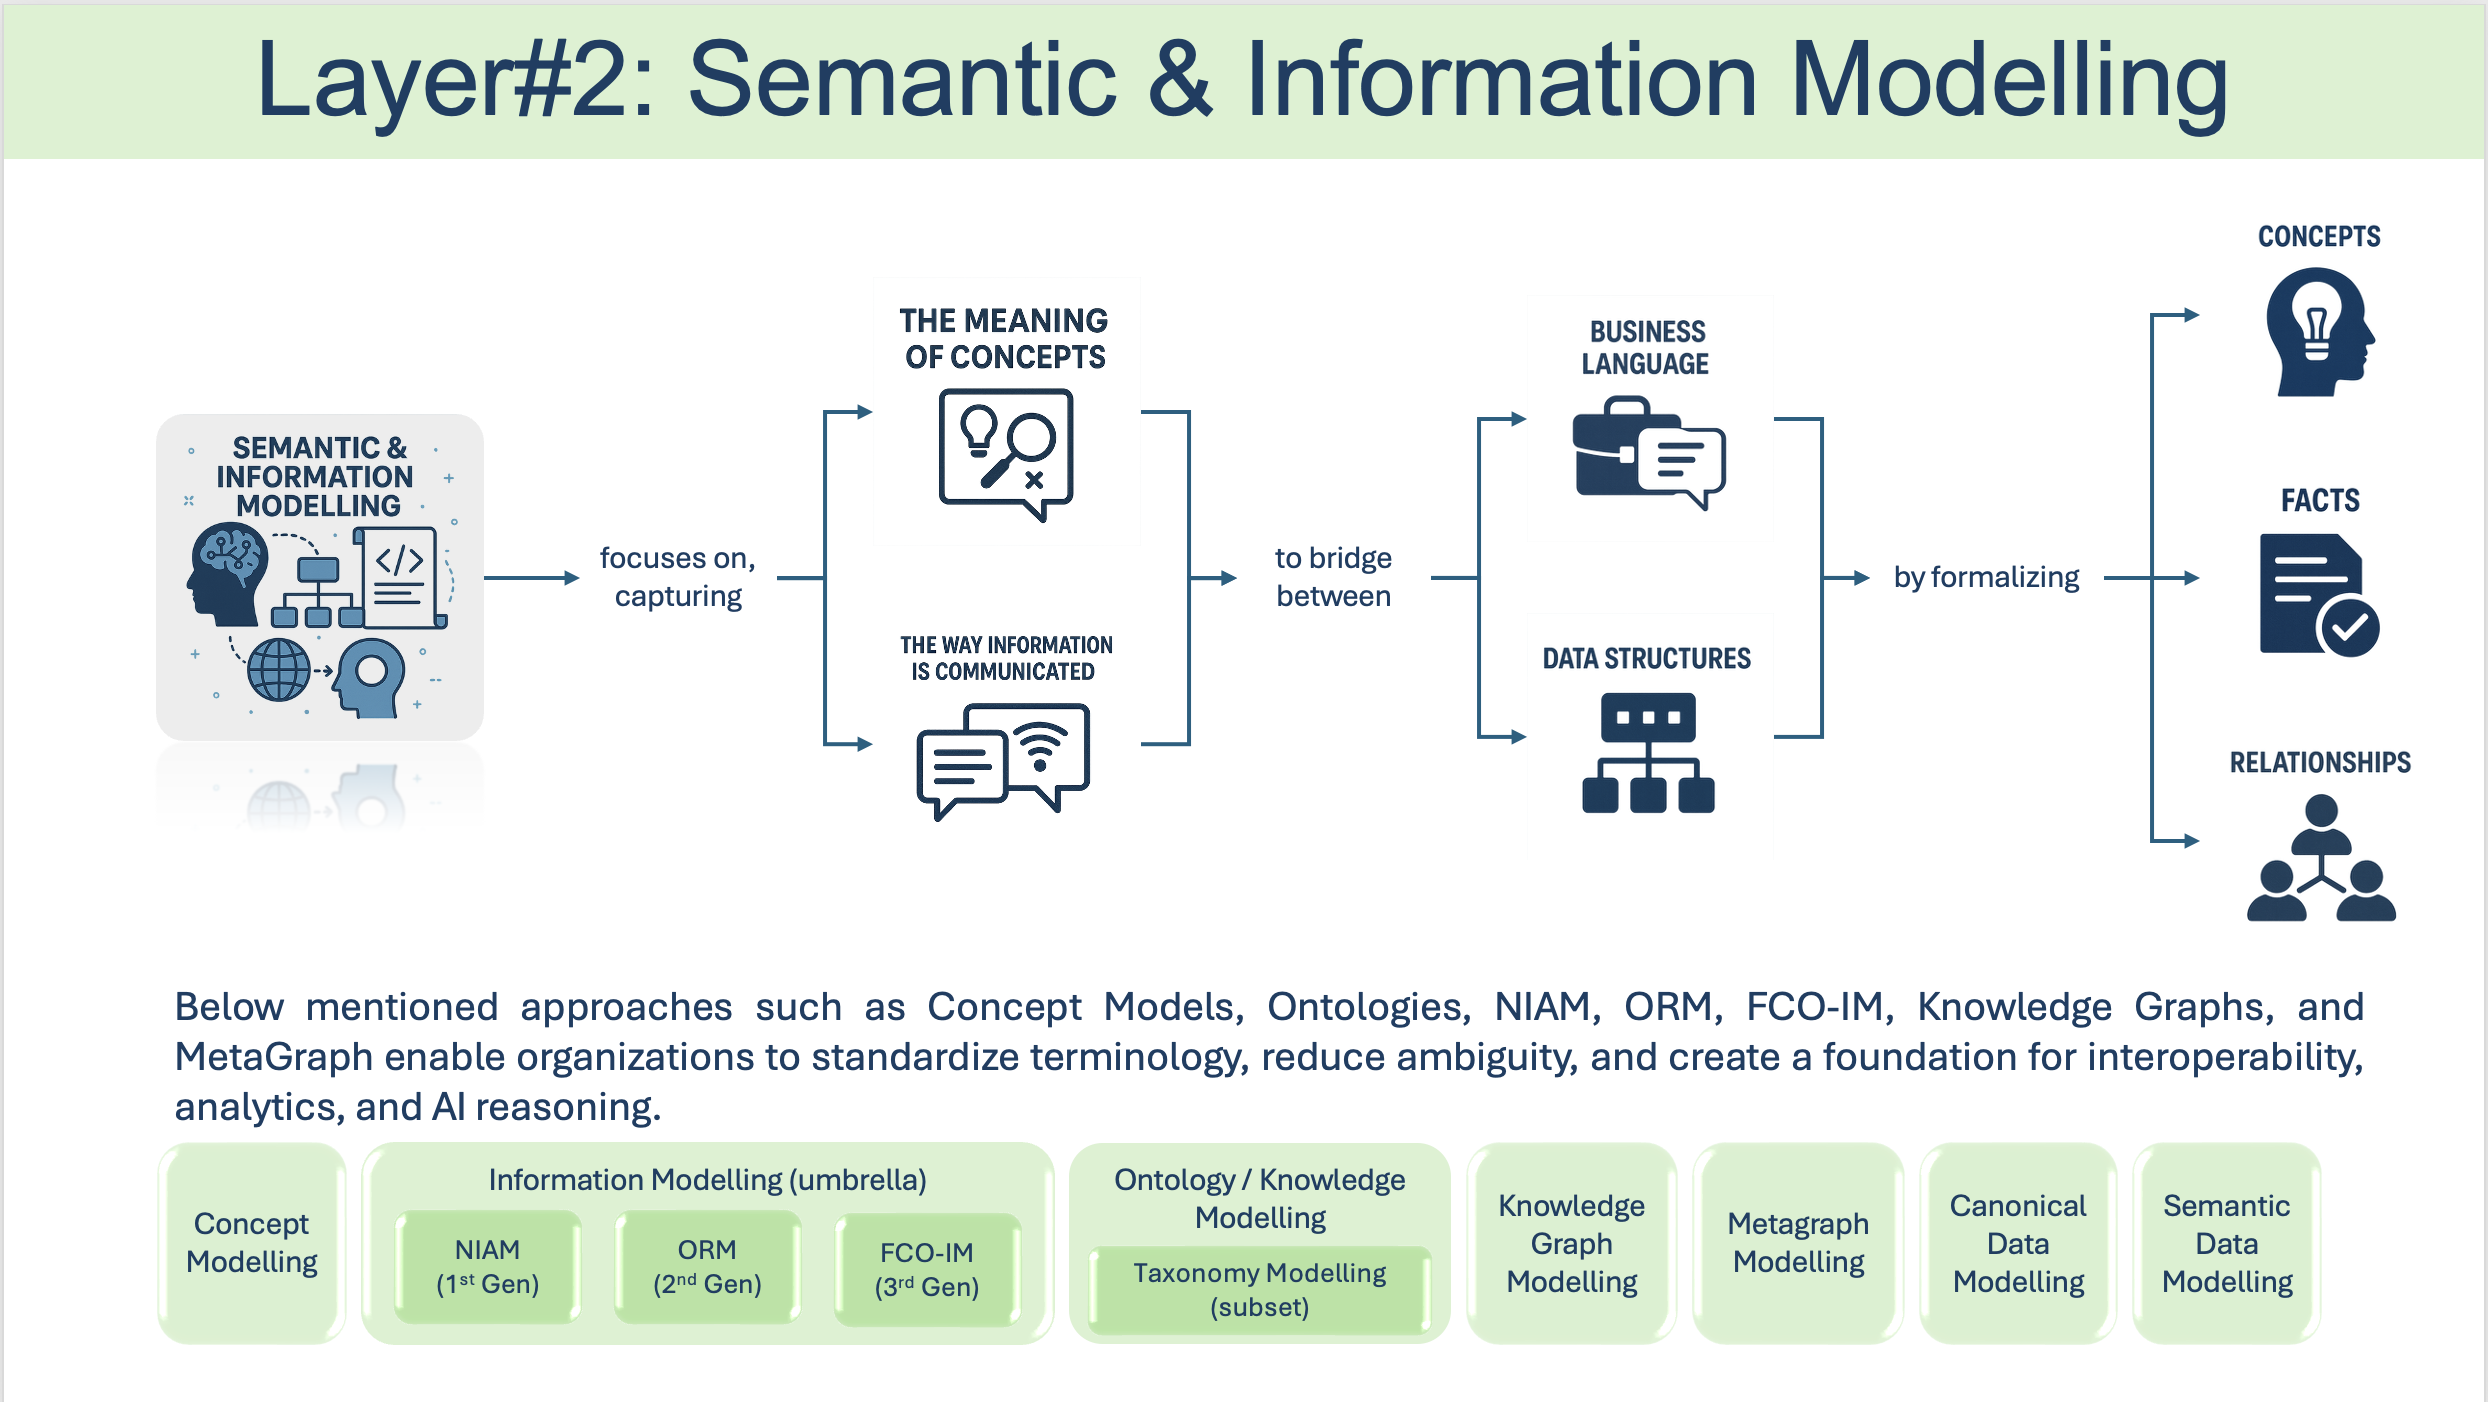
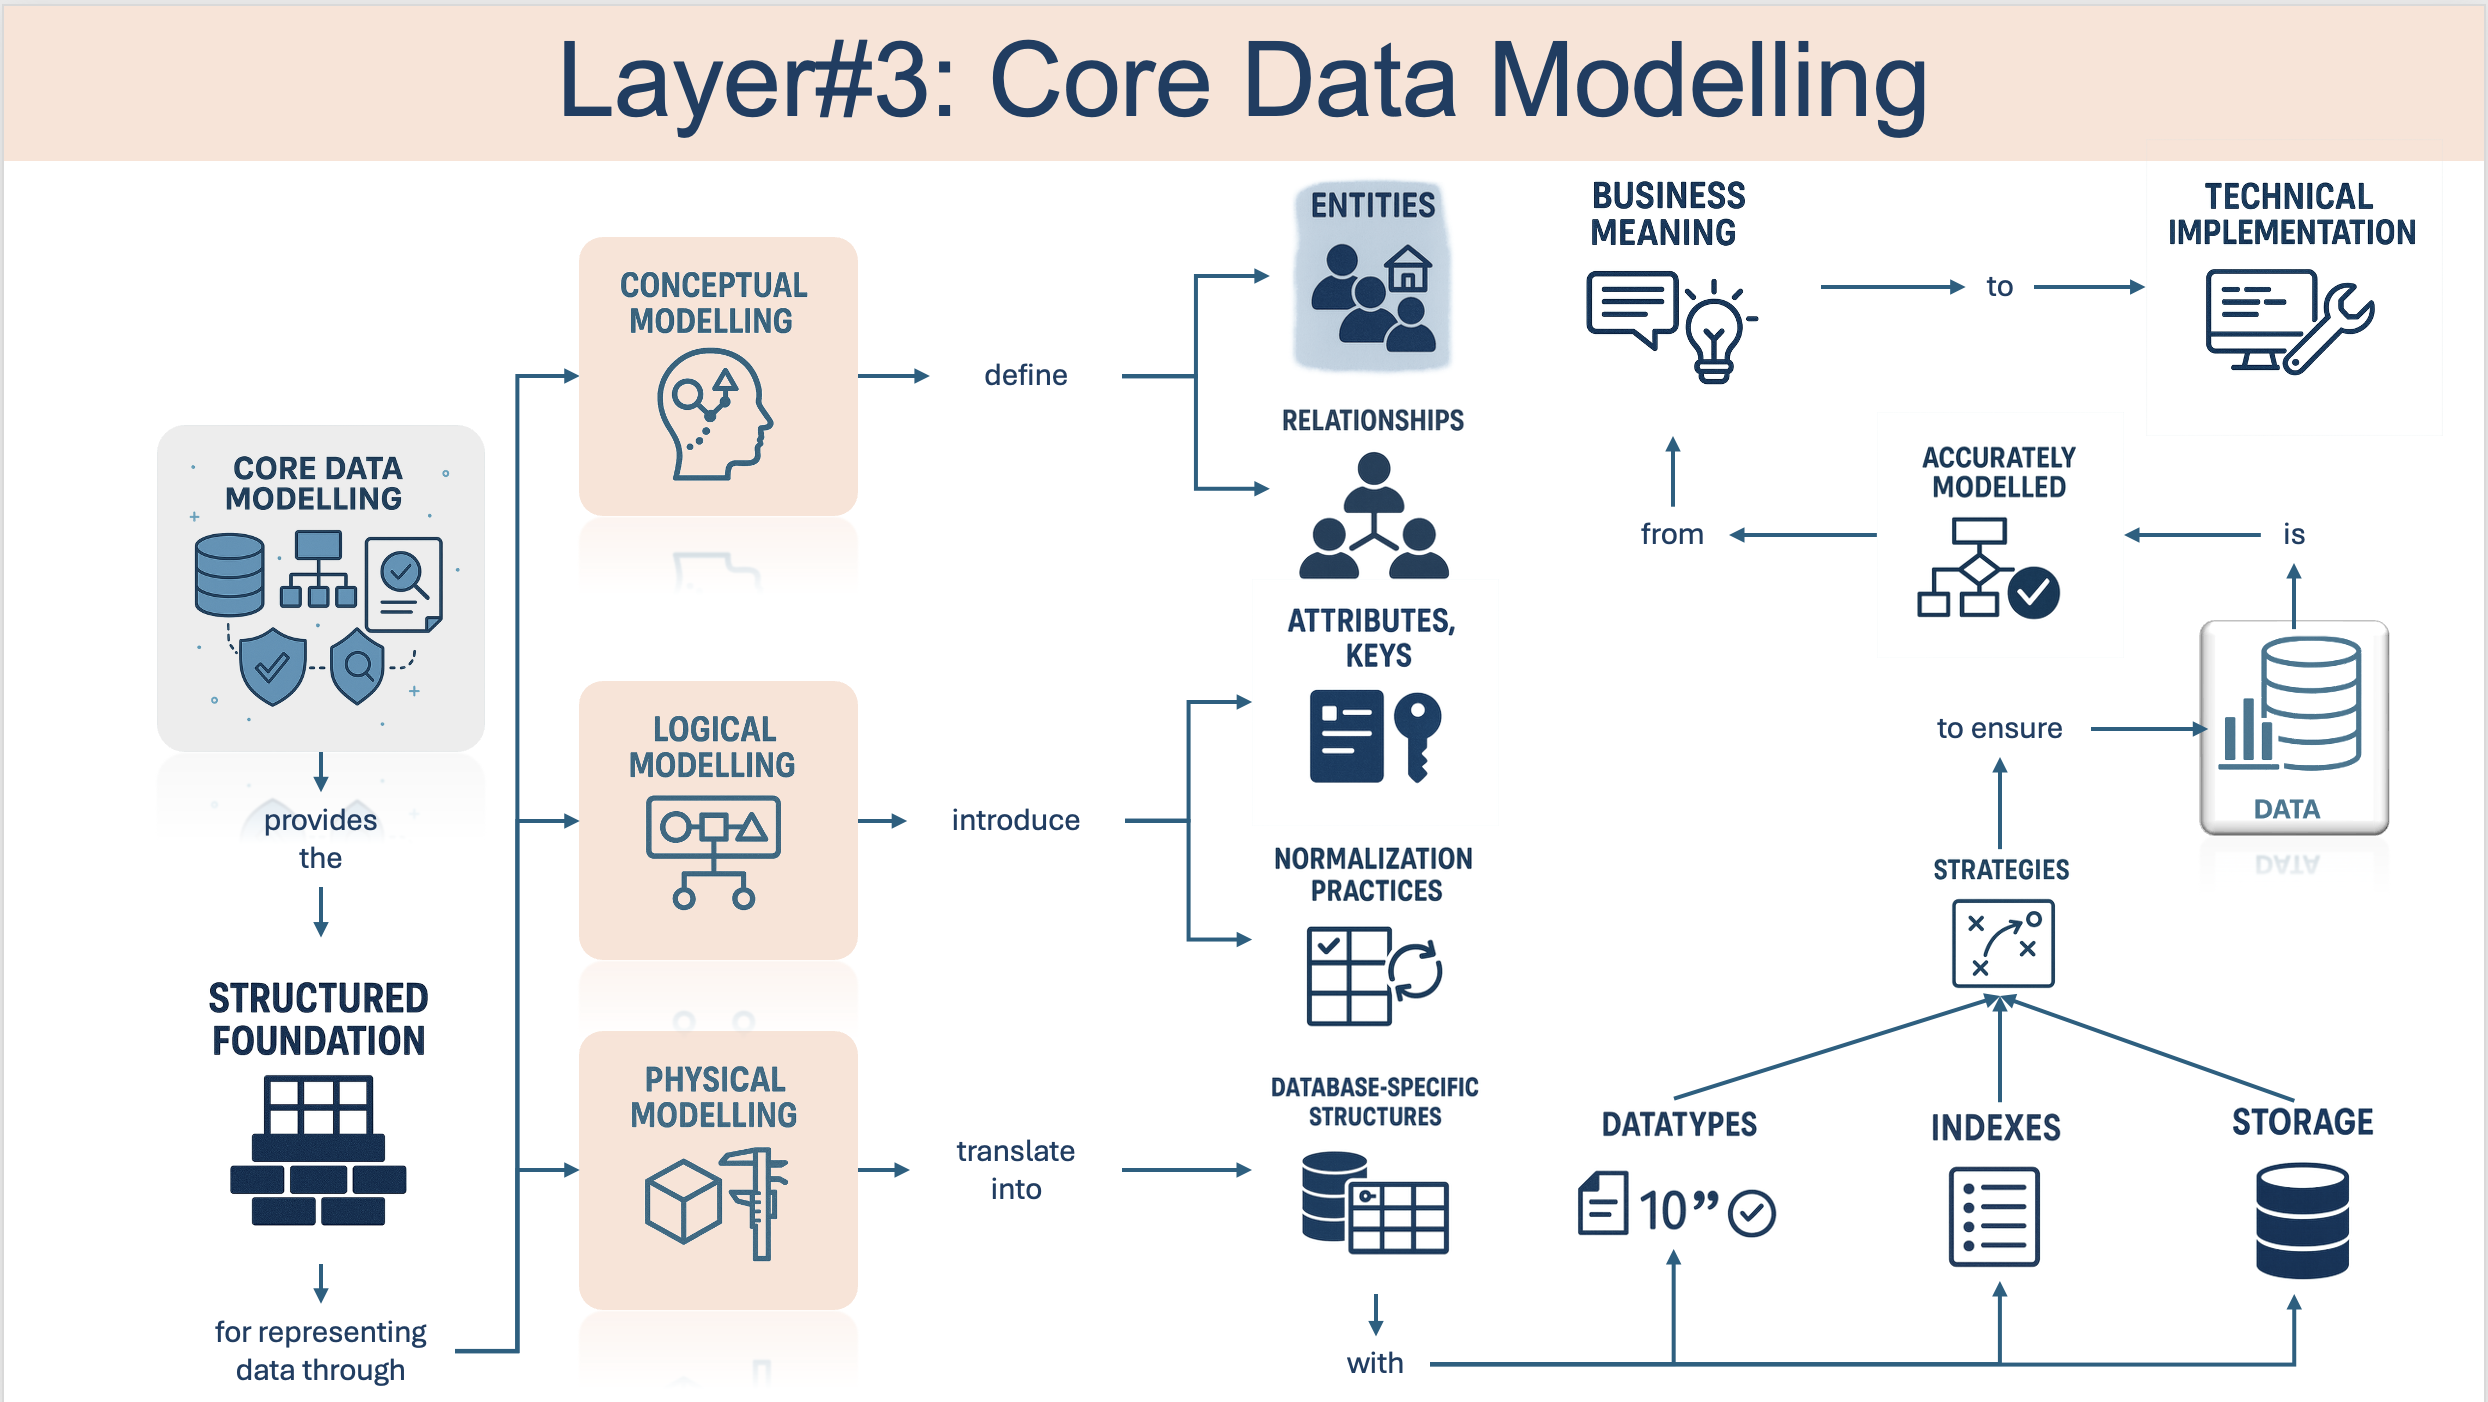
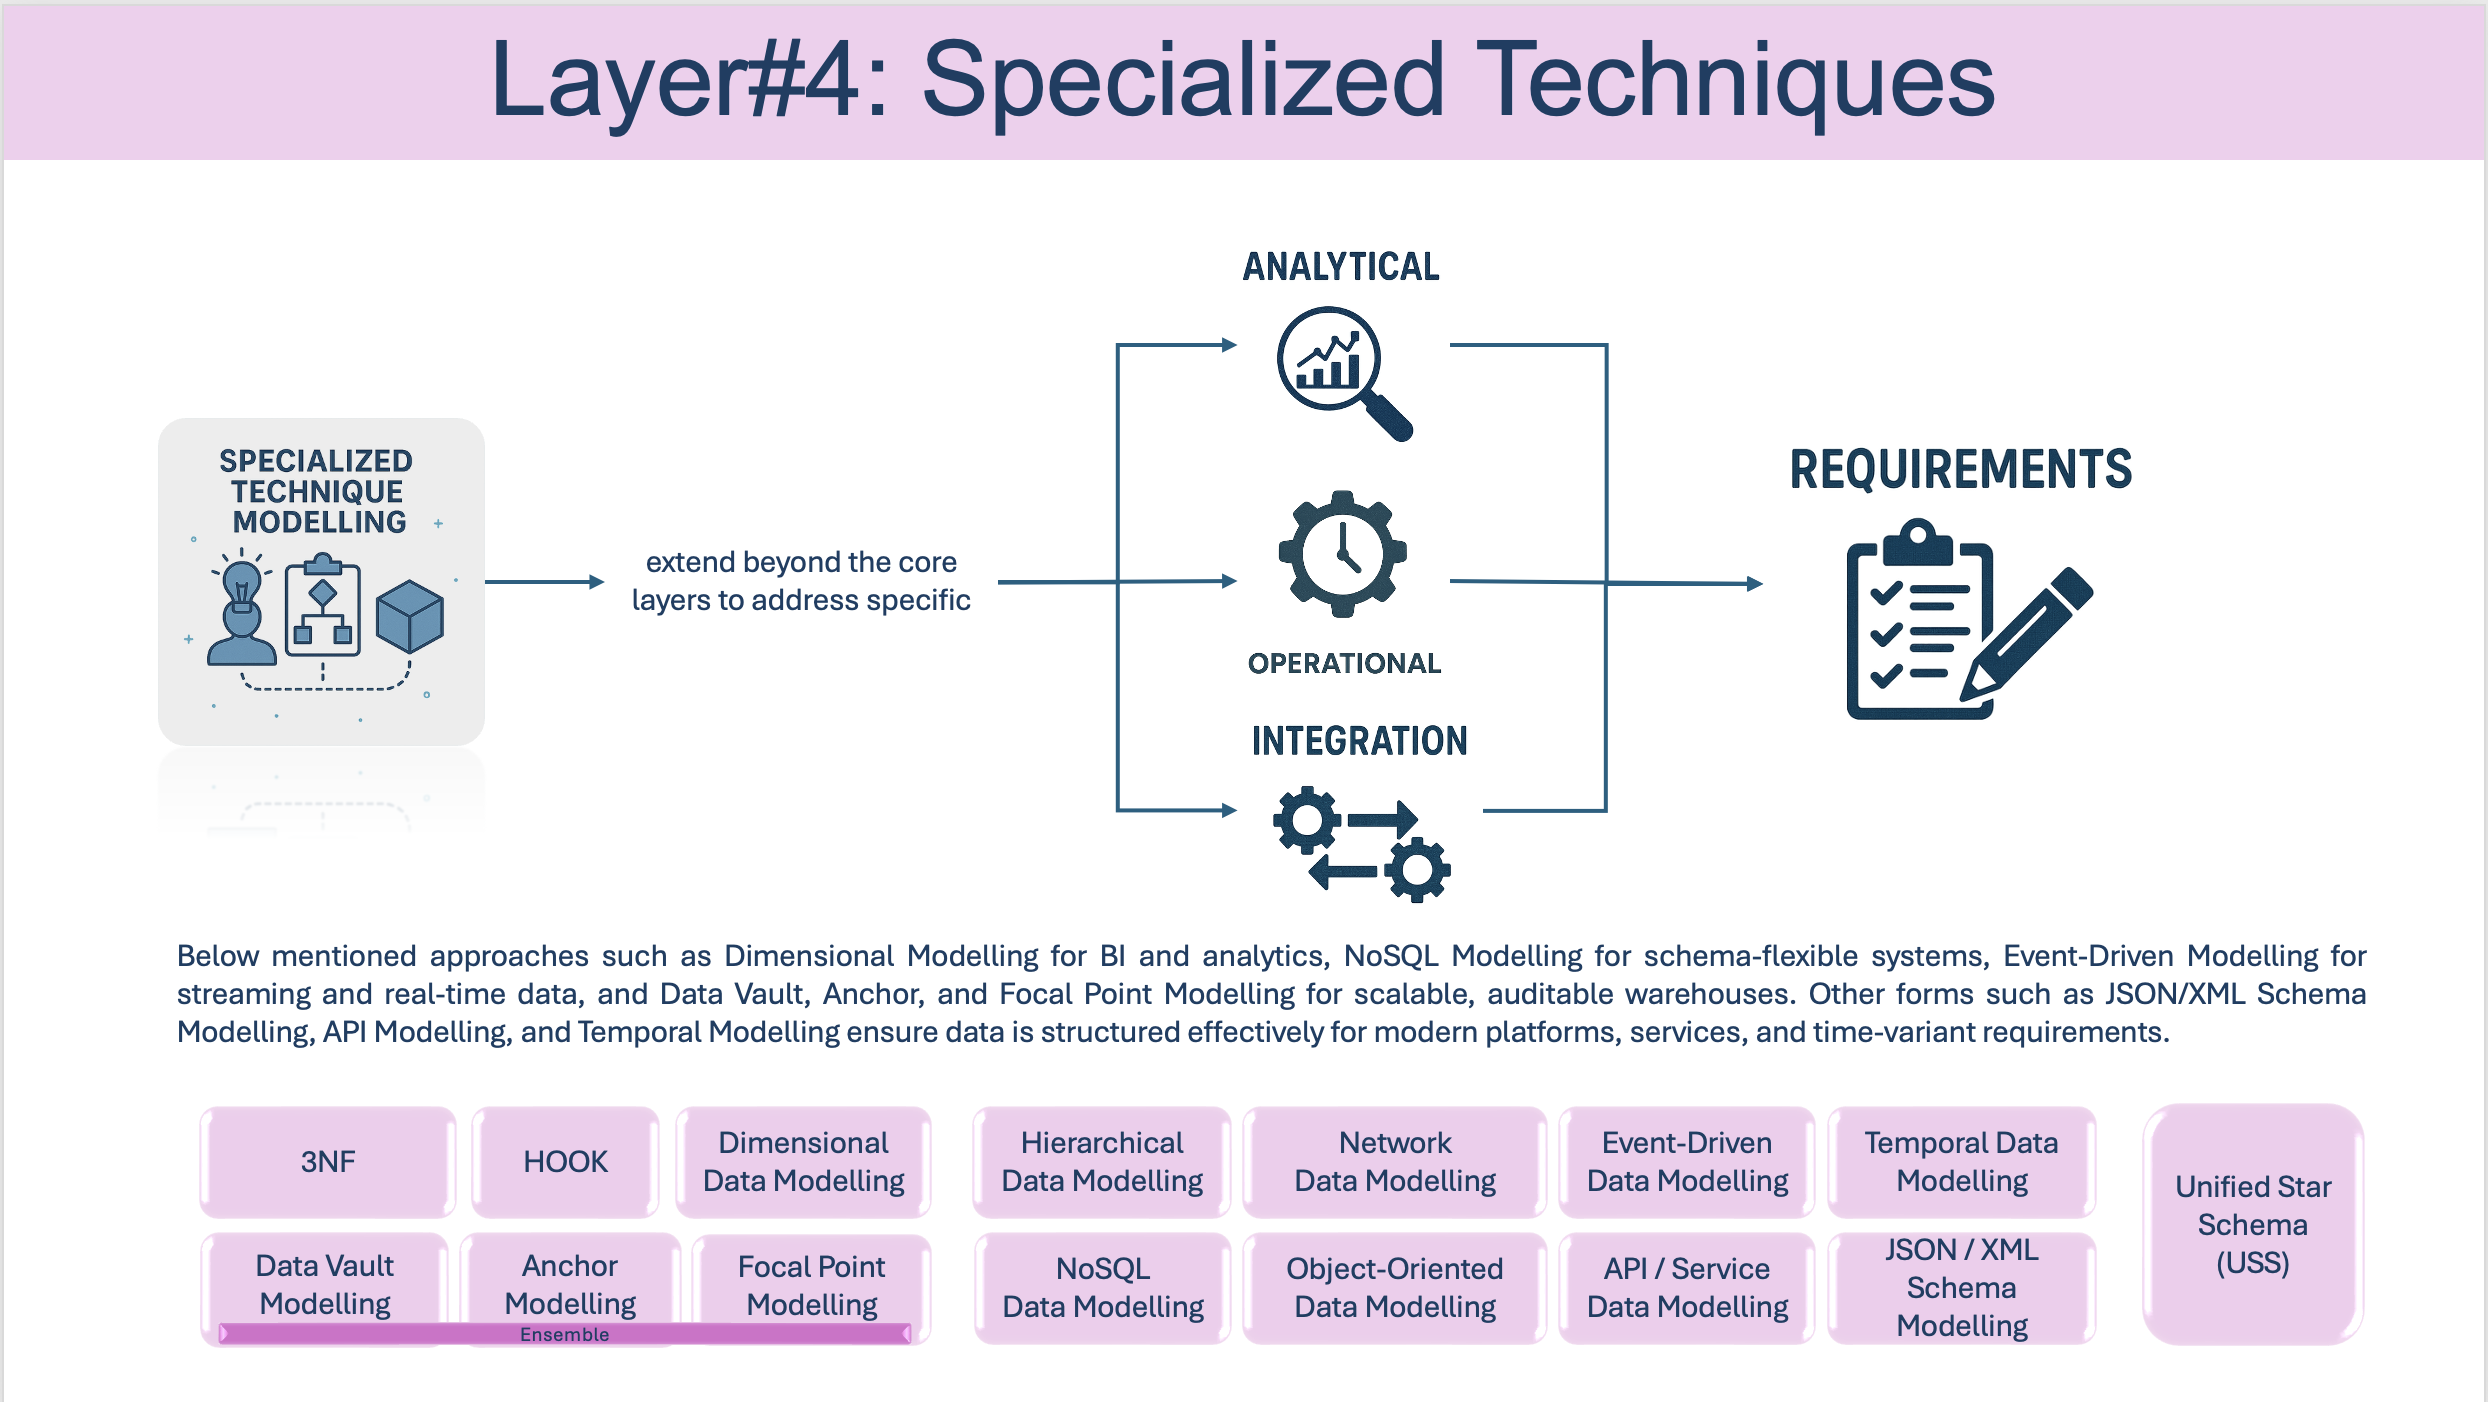
Data Modelling Layers
Flow of all Data Modelling Concepts & Techniques
Data Modelling is a foundational concept in the field of data management and analytics. It involves creating different representations of data structures to support various business and technical requirements.
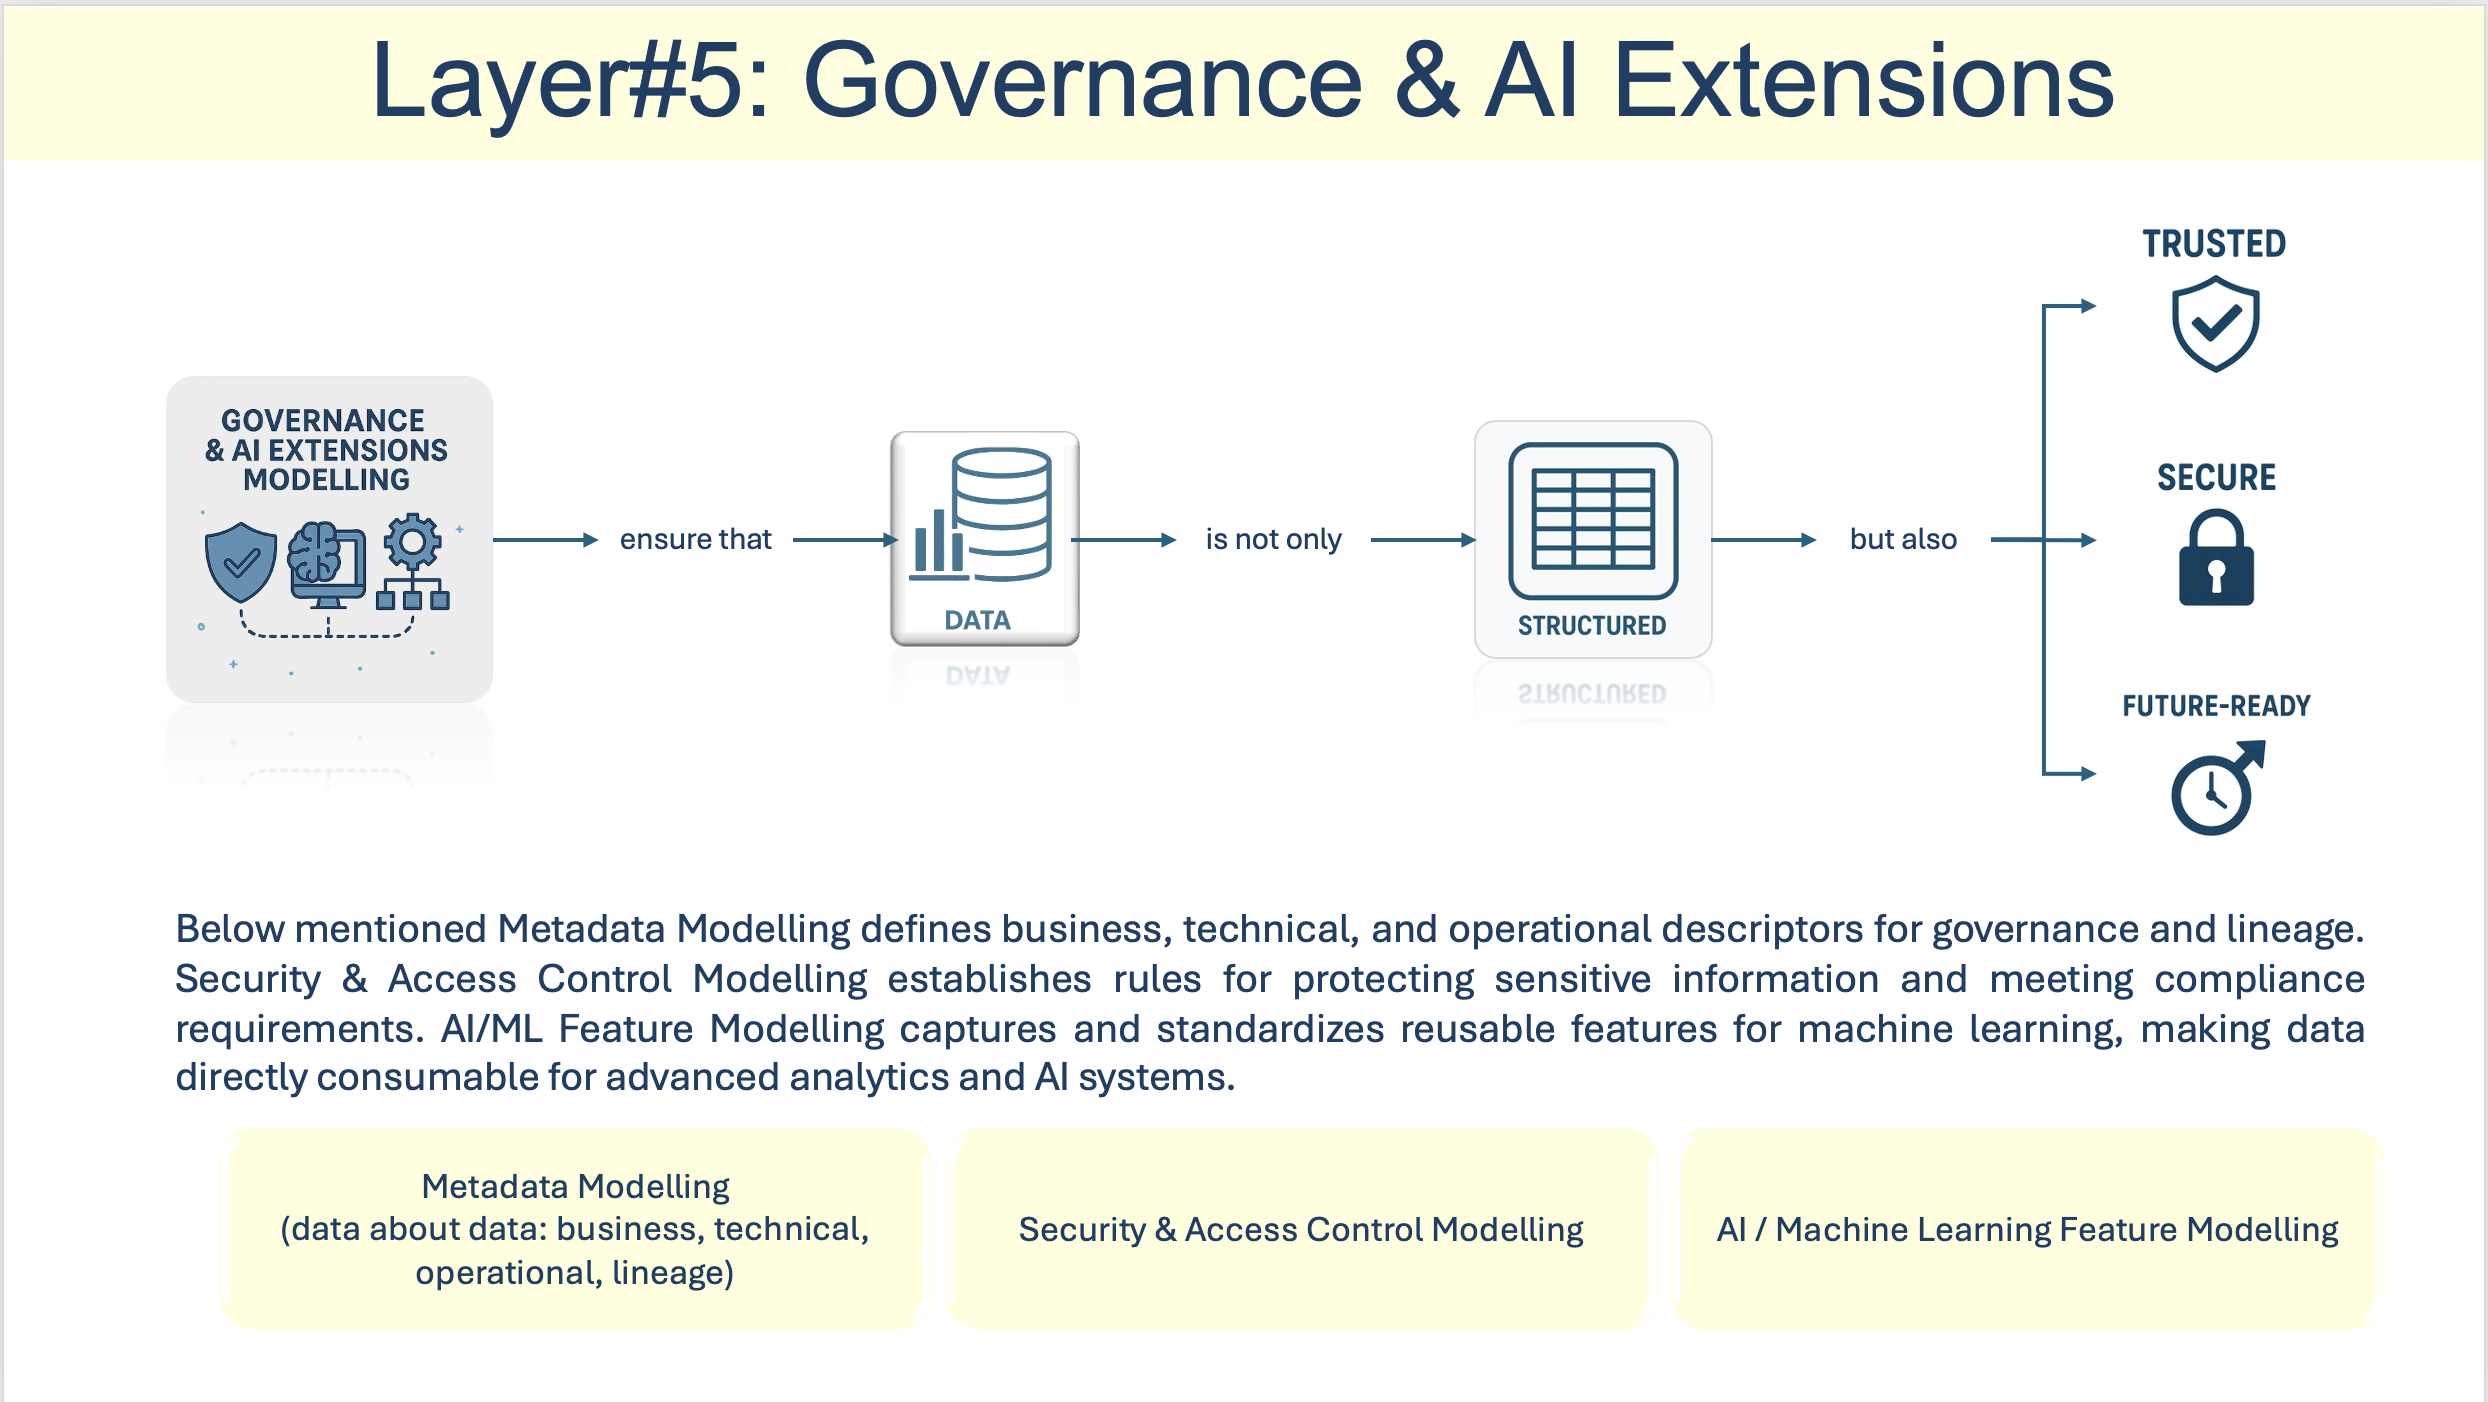
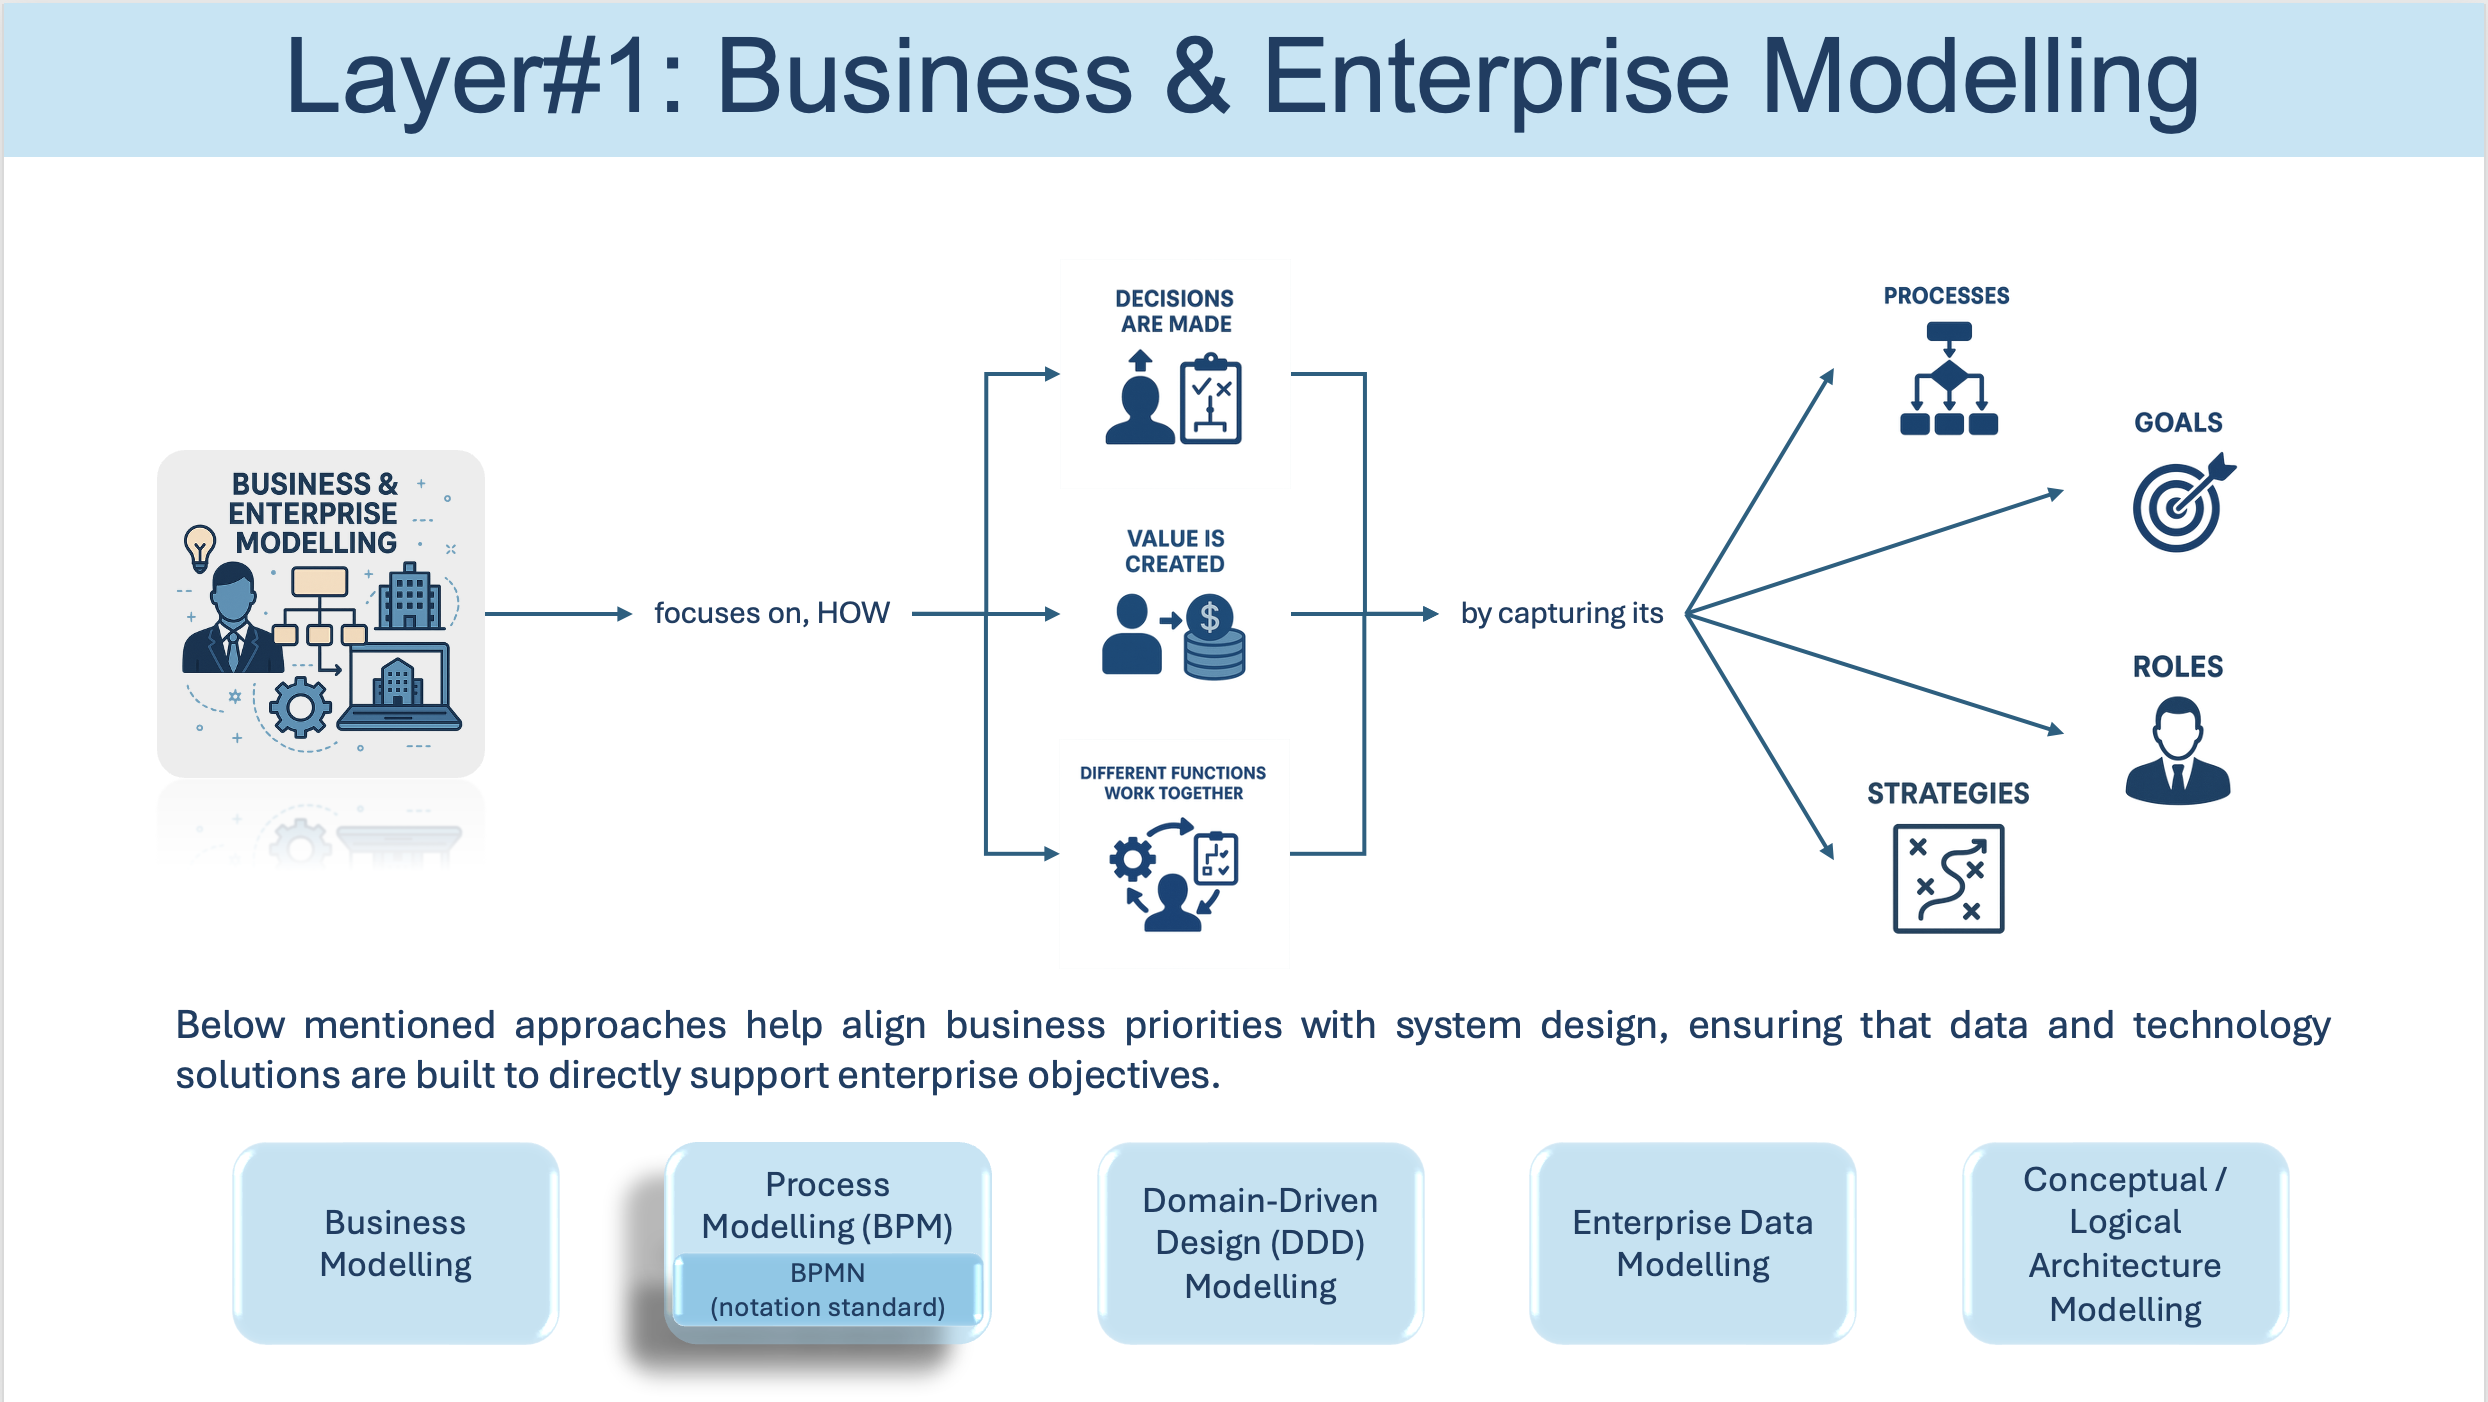
As mentioned, there are around 37 data modelling technique which can be categorized in 5 layers, mentioned below.
- Business & Enterprise Modelling
- Semantic & Information Modelling
- Core Data Modelling
- Specialized Techniques
- Governance & AI Extensions
Let’s see how all data modelling techniques get arranged in these layers.
1 min readMore
- I Am Datapedia!
Data Modeling and Design
Business Modelling
Business Modelling is the practice of understanding how an organization works as a whole. It explains how value is created, how work flows through the organization, who is involved at each step, and how decisions are made. At this stage, the focus is not on data, databases, or systems, but on the business itself. The aim is to clearly describe what the organization does and how it achieves its objectives.
The main goal of Business Modelling is to provide a complete and holistic view of the business. When this view is clear, it becomes much easier to align daily operations, management decisions, and supporting systems with the organization’s strategic goals. Without this shared understanding, systems and data solutions are often built in isolation and fail to support real business needs.
Business Modelling concentrates on the “what” and the “how” of the business. It looks at business processes, roles, responsibilities, rules, and policies. It helps answer questions such as: What activities are performed? Who performs them? What decisions are taken, and based on what rules? Because of this, Business Modelling is usually the first step before moving into information modelling and data modelling. It establishes where data is created, how it flows, and how it is ultimately used.
3 min readMore
- I Am Datapedia!
Data Modeling and Design
Process Modelling (BPM)
Process Modelling, often referred to as Business Process Modelling (BPM), is the practice of describing how work is carried out step by step inside an organization. It visually represents workflows, activities, and decision points so that everyone can clearly understand how a process starts, how it moves forward, and how it ends. Unlike Business Modelling, which explains the business at a high level, Process Modelling focuses on the actual flow of work.
The main goal of Process Modelling is to analyse and improve business processes. By clearly documenting each step, organizations can identify delays, unnecessary work, repeated tasks, or unclear responsibilities. Once these issues are visible, processes can be standardized, improved, or automated to achieve better efficiency and consistency while staying aligned with organizational objectives.
Process Modelling provides a structured way to document how work moves across people, systems, and departments. It shows who performs each task, when decisions are made, and how work is handed over from one role to another. Because of this, Process Modelling often acts as a bridge between business requirements and system design. It is commonly used as a foundation for automation, compliance checks, and process improvement initiatives.
4 min readMore
Build a strong foundation in Data & AI
Follow the Data Foundations learning path (Beginner to Advanced).