Once you sign in, your details will show here.
Knowledge Hub
Your Reading List
Sign in to see your reading list.
Topics you save will appear here.
+ New Topic
Filter
DAMA Knowledge Area
Learning Level
Content Type
Sort
Every topic is free to read. A free account also lets you search the topics, react to a topic and comment under it.
- I Am Datapedia!
Data Integration and Interoperability
Data Interchange
Data Interchange refers to the electronic exchange of information or data between different computer systems, applications, or software. It involves the transmission and reception of structured data to enable seamless communication and integration between disparate systems.
Few Key Points:
- Structured Data Exchange: Data interchange involves the exchange of structured data, often in a standardized format that both the sending and receiving systems can understand.
- Cross-Platform Communication: It facilitates communication between diverse platforms, applications, or software that may have different data structures or operate in distinct environments.
- Standards and Formats: To ensure interoperability, data interchange often relies on industry standards and common formats. Examples include XML (eXtensible Markup Language), JSON (JavaScript Object Notation), or specific data exchange standards in various industries.
- Facilitates Integration: Data Interchange plays a crucial role in integrating different systems and enabling them to work together cohesively. It allows for the sharing of information between applications, databases, or even organizations.
2 min readMore
- I Am Datapedia!
Data Storage and Operations
Data Replication
Data Replication is the process of creating and maintaining multiple copies of the same dataset in different locations or systems. The goal is to ensure data availability, improve fault tolerance, and enhance performance by distributing data across various storage locations. Replicated data can be synchronized in real-time or at scheduled intervals to keep the copies consistent.
For example, imagine you and your classmates are working on a group project, and you need to share a document with everyone. Instead of having a single copy stored on one person's computer, you decide to use data replication to ensure that everyone has access to the most up-to-date version.
Here's how it works:
- Initial Copy: You create a document on your computer with the project details. This is the initial copy.
- Replication: You decide to replicate the document by making copies and distributing them to each group member. Now, everyone has their own copy of the document.
- Changes and Updates: As the project progresses, different group members make changes to their copies based on their contributions. For example, one person adds information about research findings, another updates the formatting, and so on.
- Synchronization: Periodically, or when major changes occur, you decide to synchronize the copies. This means that everyone shares their updates, and each person gets the latest version of the document. This ensures that all copies are consistent and reflect the most recent changes.
2 min readMore
- I Am Datapedia!
Data Governance
Data Value Realization
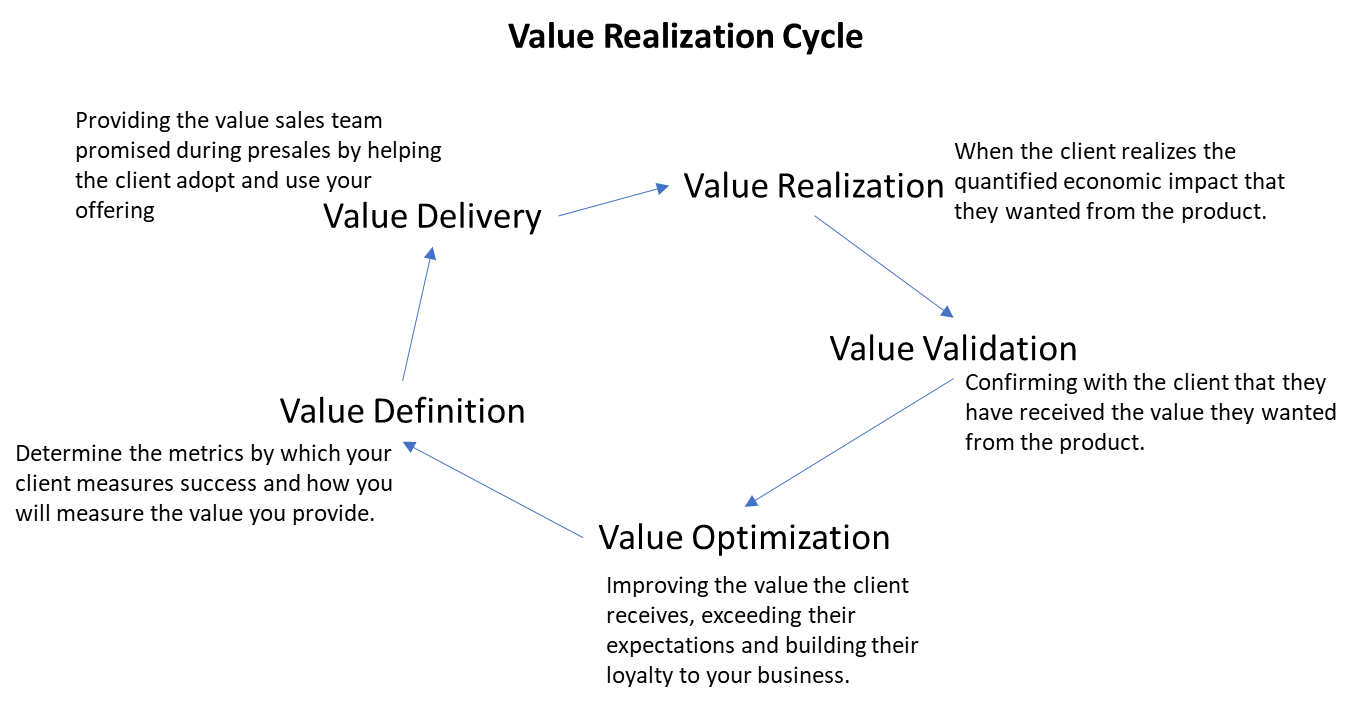
Data Value Realization refers to the importance, usefulness, or significance of data in achieving organizational goals or objectives.
It implies the actualization or fulfillment of something. Putting these together, "Data Value Realization" suggests the process or action of actualizing or realizing the value inherent in data. This involves strategies, practices, or initiatives aimed at leveraging data to achieve tangible benefits or outcomes.
- Effective Use of Data: Implementing practices to ensure that data is effectively used to derive insights, make informed decisions, and drive positive outcomes.
- Monetization of Data: Extracting economic value from data, for example, by identifying opportunities for new revenue streams or cost savings through data-driven initiatives.
- Achieving Business Objectives: Aligning data initiatives with broader business goals and realizing the value of data in achieving those objectives.
- Enhancing Decision-Making: Utilizing data to enhance decision-making processes, optimize operations, and improve overall business performance.
4 min readMore
- I Am Datapedia!
Data Governance
Data Strategy vsData Implementation
Data Strategy refers to the overarching plan and vision that an organization establishes to manage, govern, and leverage its data assets effectively. It is a high-level, long-term approach that aligns data initiatives with business objectives. It emphasizes the organization's goals, priorities, and desired outcomes related to data. It involves understanding the value of data, defining data governance practices, establishing data quality standards, and aligning data initiatives with business strategies.
Key Components:
- Vision and Objectives: Defines the purpose and goals of leveraging data within the organization.
- Governance Framework: Establishes policies and procedures for managing and securing data.
- Data Quality Standards: Sets guidelines for ensuring accuracy, completeness, and reliability of data.
- Data Lifecycle Management: Defines how data is created, stored, used, and retired over time.
- Technology Roadmap: Outlines the technologies and infrastructure needed to support data initiatives.
3 min readMore
- I Am Datapedia!
Data Governance
Data Doom Pile
In the data world, a "DATA DOOM PILE" is likened to a collection of unorganized or miscellaneous data items that need attention and organization. It's comparable to the concept of having a repository for data that requires sorting, cleansing, or processing at a later time. Similar to how individuals have physical spaces like a junk drawer or cluttered area for miscellaneous items, in the data context, there are repositories, folders, or databases where unstructured or unprocessed data accumulates before being properly managed or analyzed. These are referred to as "data doom piles," reflecting the need for organization and attention in the data management process.
In the data world, a "DATA DOOM PILE" is like a virtual space where various pieces of unorganized data accumulate, waiting to be properly sorted and managed.
Let's explore this concept with examples that we can relate to:
- Unsorted Data Files on a Computer: Imagine you have a folder on your computer called "Data Doom Pile." In this folder, you may have random files, photos, or documents that you haven't organized yet. These could be data from school projects, downloaded files, or photos from your camera that need categorization.
- Uncategorized Emails in Your Inbox: Think of your email inbox as a "Data Doom Pile." You receive various emails with attachments, links, and information. Some of these emails may be important, but others are just sitting there, waiting to be categorized, archived, or deleted.
- Unprocessed Survey Responses: Suppose you conducted a survey with classmates, and their responses are in a spreadsheet. If you haven't yet analyzed or organized the data to draw conclusions, that spreadsheet can be considered a "Data Doom Pile" of survey responses.
- Raw Data from Science Experiments: In a science class, after conducting experiments and collecting data, you might have a notebook or digital file with raw data. Before you analyze and present your findings, raw data represents a "Data Doom Pile."
- Images in an Unorganized Gallery: If you have a collection of photos on your phone or computer that you haven't sorted into albums or categorized, that assortment can be your "Data Doom Pile" of images.
- Unprocessed Sensor Readings: In a science or engineering project involving sensors, you might collect data from various sensors. If you haven't yet processed or interpreted those readings, the dataset can be viewed as a "Data Doom Pile" waiting for analysis.
3 min readMore
- I Am Datapedia!
Data Governance
Data Collaboration
Data Collaboration in the data world refers to the practice of sharing and working with data across individuals, teams, departments, organizations, or even between different systems to achieve common goals, solve problems, or generate insights. It involves cooperative efforts in handling, analyzing, and deriving value from data assets. Data Collaboration is essential for fostering innovation, improving decision-making, and addressing complex challenges that may require diverse perspectives and expertise.
Key aspects of Data Collaboration include:
- Sharing Data: Organizations and individuals share data sets, information, or insights with one another. This can include internal data sharing within an organization or external sharing between different entities.
- Interdisciplinary Cooperation: Data Collaboration often involves collaboration between individuals with diverse skills and expertise. For example, data scientists, analysts, domain experts, and business professionals may collaborate to extract meaningful insights from data.
- Data Integration: Integrating data from various sources to create a unified view. This could involve merging datasets, connecting databases, or using middleware to facilitate seamless data exchange.
- Secure Data Exchange: Ensuring that data sharing is done securely and in compliance with privacy regulations. This involves implementing measures to protect sensitive information during the collaboration process.
- Open Data Initiatives: Participation in open data initiatives where organizations contribute and access shared datasets for the benefit of the wider community or industry.
- Cross-Functional Projects: Collaborative projects that span different functions or departments within an organization. For example, marketing, finance, and operations teams working together on a data-driven project.
- Data Standards and Governance: Establishing data standards and governance practices to ensure consistency, quality, and reliability of shared data. This helps in maintaining trust among collaborators.
3 min readMore
- I Am Datapedia!
Data Governance
Data Tech Debt
Technical Debt, often abbreviated as "tech debt," is a metaphorical concept in software development that refers to the implied cost of additional work created when software is built or modified in a way that prioritizes short-term goals or speedy delivery over long-term sustainability. It is similar to financial debt, where you borrow money with the understanding that you will pay it back with interest.
Technical debt arises when developers choose a quick and easy solution that may solve an immediate problem but is not necessarily the best or most efficient in the long run. This can result from factors such as tight deadlines, evolving requirements, or a need for rapid prototyping.
There are several types of technical debt, including:
Code Debt: Poorly written or poorly structured code that might work but is difficult to understand, maintain, or extend.
Design Debt: Rushed or inadequate system or software architecture that may lead to inefficiencies, difficulties in adding new features, or challenges in maintaining the system.
6 min readMore
- I Am Datapedia!
Data Governance
Data Ownership vsData Governance
Data Ownership and Data Governance are related concepts in the broader field of data management, but they refer to different aspects of handling and overseeing data within an organization.
Let's explore the distinctions between data ownership and data governance:
Data Ownership: It is the concept that defines the rights and responsibilities associated with data. It specifies who has control over the data, including the authority to make decisions regarding its collection, storage, access, and usage.
- It is often tied to individuals or organizational units within a company.
- The data owner is accountable for ensuring that data is handled in compliance with relevant laws, regulations, and internal policies.
- It is more focused on the "who" aspect of data control, determining who has the ultimate say over the data.
Data Governance: It is a broader framework and set of practices that ensure high data quality, availability, usability, and security within an organization. It involves the establishment of policies, procedures, and roles to manage and control data throughout its lifecycle.
2 min readMore
- I Am Datapedia!
Data Storage and Operations
Data Archiving
Data Archiving involves the long-term storage and preservation of data that is no longer actively used but may still be valuable for future reference or compliance purposes. This process helps organizations manage their data lifecycle efficiently, ensuring that important information is retained for historical, legal, or regulatory reasons.
Here are a few key elements of statistics archiving:
- Retaining Historical Data: It is a fundamental aspect of data archiving. This involves preserving information that may not be actively used but has historical significance or provides a record of past events. This can include anything from academic records and research findings to historical business transactions.
- Compliance and Legal Requirements: It is a critical consideration in data archiving. Organizations must adhere to specific legal requirements that mandate the retention of certain types of data for predefined periods. This ensures that the organization remains in compliance with industry standards and legal frameworks.
- Reducing Active Storage Costs: Data archiving helps in optimizing storage costs by moving less frequently accessed or older data from high-performance storage systems to more cost-effective storage solutions. This practice ensures that valuable storage resources are reserved for active and frequently accessed data.
- Preserving Research Data: It is essential for scientific and academic institutions. Archiving experimental data and research findings allows researchers to revisit and validate their work. It contributes to the integrity of scientific endeavors, enabling the reproduction of experiments and the advancement of knowledge.
- Managing Email Archives: Email archives play a crucial role in managing organizational communication. Archiving old emails helps organizations free up space on active email servers, ensuring efficient email management. Archived emails may also be accessed when needed for legal, compliance, or historical purposes, maintaining a comprehensive record of communications.
3 min readMore
- I Am Datapedia!
Data Storage and Operations
Data Compression
Another often overlooked subject is particularly significant in the age of Big Data, where the substantial influence of unstructured data on cloud storage costs is evident. In this era, recognizing the importance of data compression is essential; neglecting its utilization translates to unnecessary expenditures and extended return on investment timelines.
Let’s decode it…..
Data compression is a method of decreasing the size of files or data to save storage space and communication bandwidth. It involves encoding information using fewer bits than the original representation.
Here's a simple explanation with examples:
- Text Compression:
- Imagine you have a text file with the sentence: "The quick brown fox jumps over the lazy dog."
- Without compression, each character is represented by a certain number of bits (usually 8 bits per character in ASCII). A lot of space can be taken up by this.
- Through compression, you can replace commonly used words or phrases with shorter codes. For instance, you might replace "the quick brown fox jumps over" with a single code. When decompressed, the original sentence is reconstructed.
- Image Compression:
- Consider a digital image with millions of pixels, each represented by color information (e.g., RGB values).
- Compression techniques reduce redundancy in the image. Instead of storing each pixel's color separately, you might store patterns or use mathematical transformations to represent the image more efficiently.
- JPEG is a common image compression format that achieves significant file size reduction while maintaining reasonable image quality.
- Audio Compression:
- In the case of audio, there is a vast amount of data in a music file, especially in high-quality formats.
- Audio compression algorithms, like MP3, remove redundant or less perceptually important information. They take advantage of the fact that our ears are less sensitive to certain frequencies and remove data that may not be noticeable to the listener.
- Lossless vs. Lossy Compression:
- Lossless compression retains all the original data when decompressed. It's like zipping a file and then unzipping it, what you get back is exactly the same as what you started with.
- Lossy compression sacrifices some information to achieve higher compression ratios. For example, in JPEG compression, some details in an image might be lost, but the trade-off is a much smaller file size.
- Compression in Everyday Technology:
- When you download a ZIP file from the internet, you're using a form of data compression. The ZIP file contains your files in a compressed form, and when you unzip it, the original files are restored.
- Streaming services use compression to transmit audio and video efficiently, allowing you to watch videos or listen to music without having to download huge files.
3 min readMore
- Text Compression:
Build a strong foundation in Data & AI
Follow the Data Foundations learning path (Beginner to Advanced).